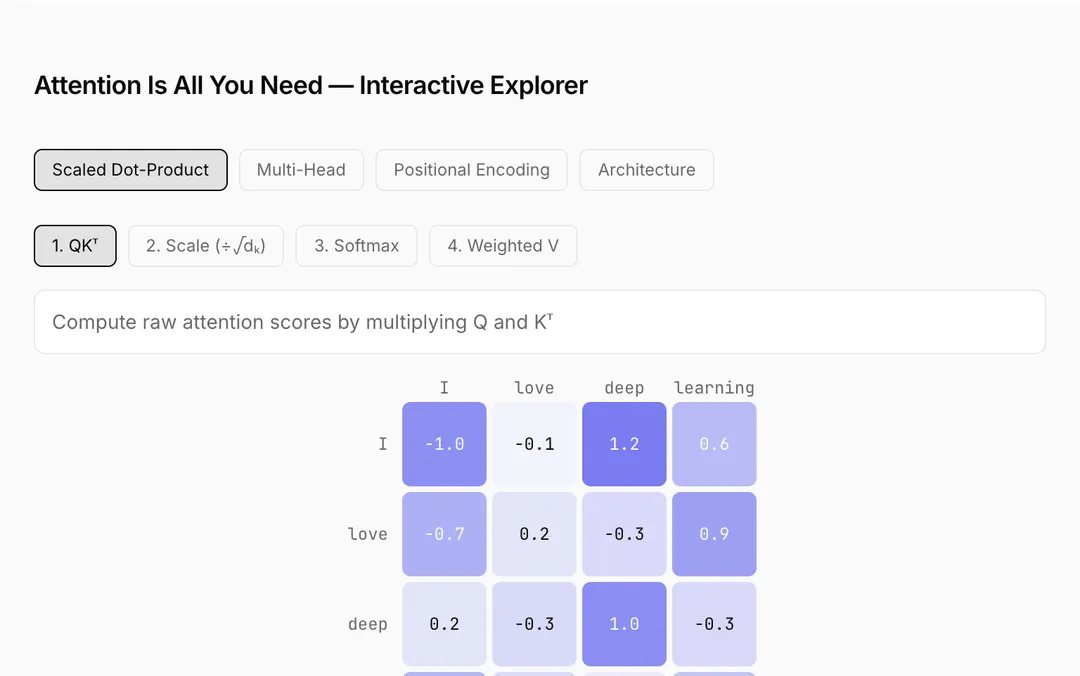
Paper2017
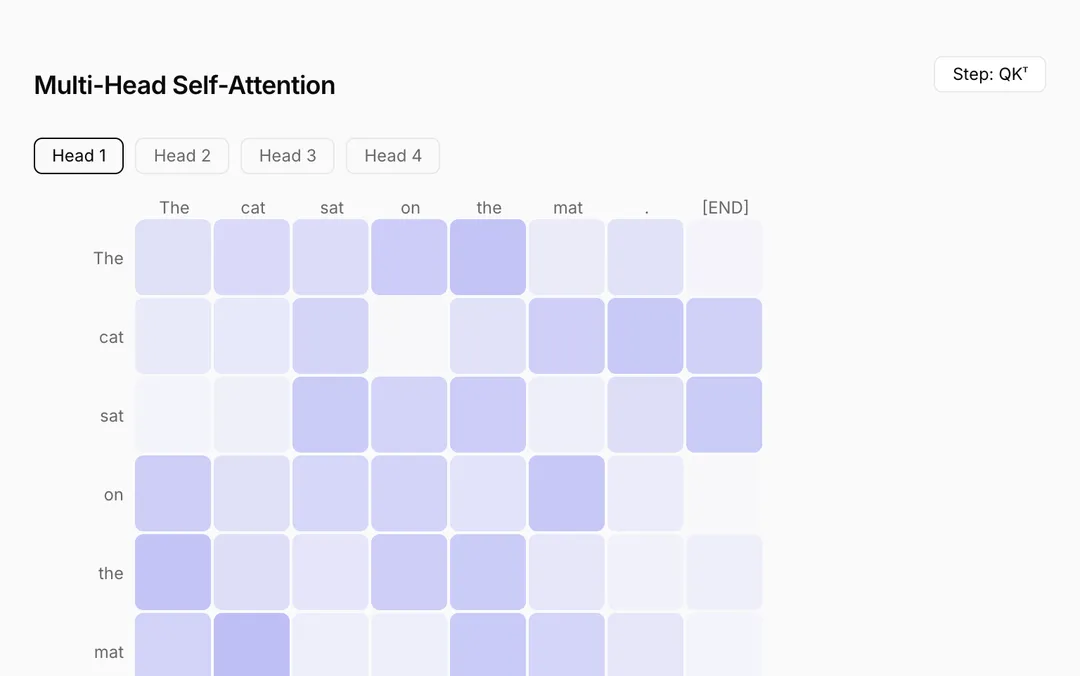
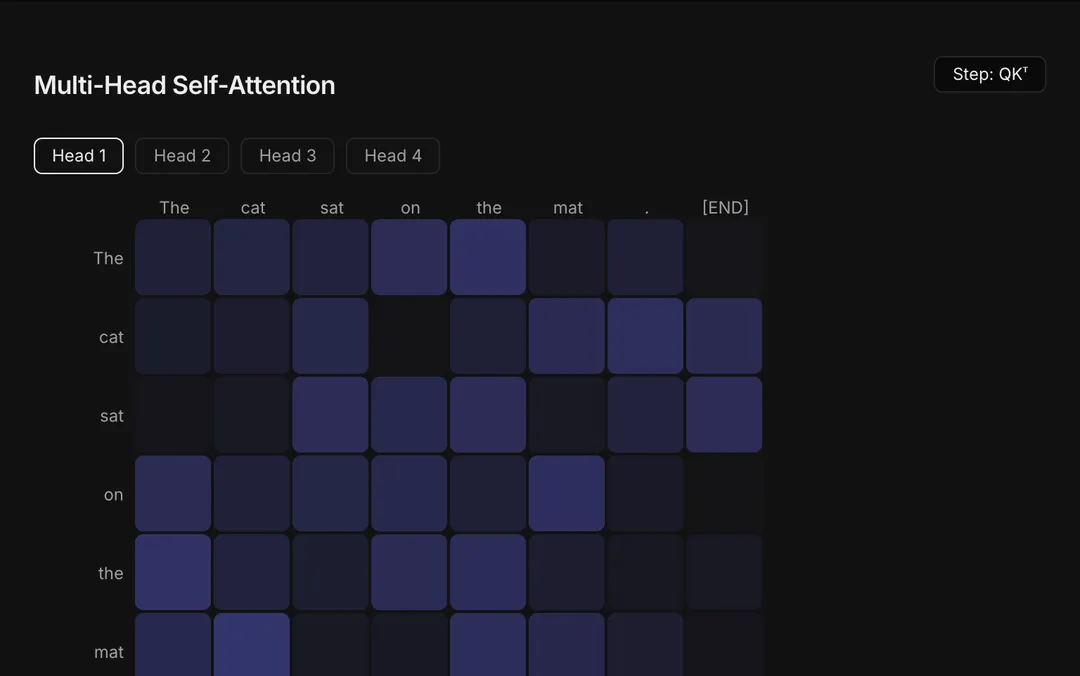
Attention Is All You Need
Vaswani et al.
The 2017 paper that introduced the Transformer architecture
8 entries / Filter in the index →
Paper2017
Vaswani et al.
The 2017 paper that introduced the Transformer architecture
Paper2023
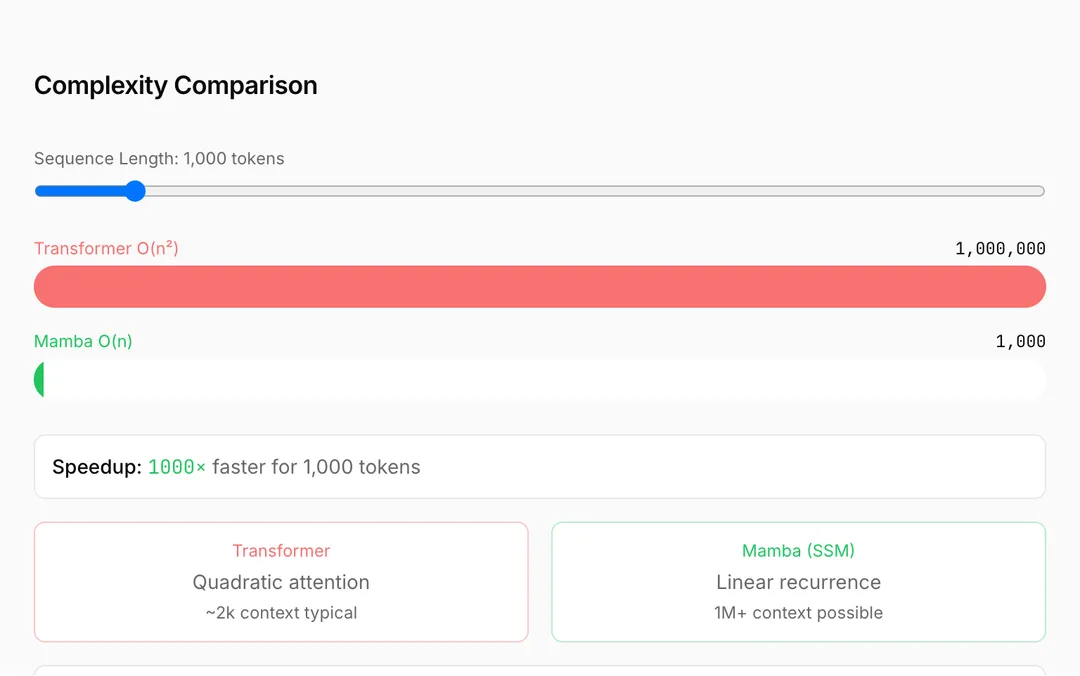
Gu & Dao
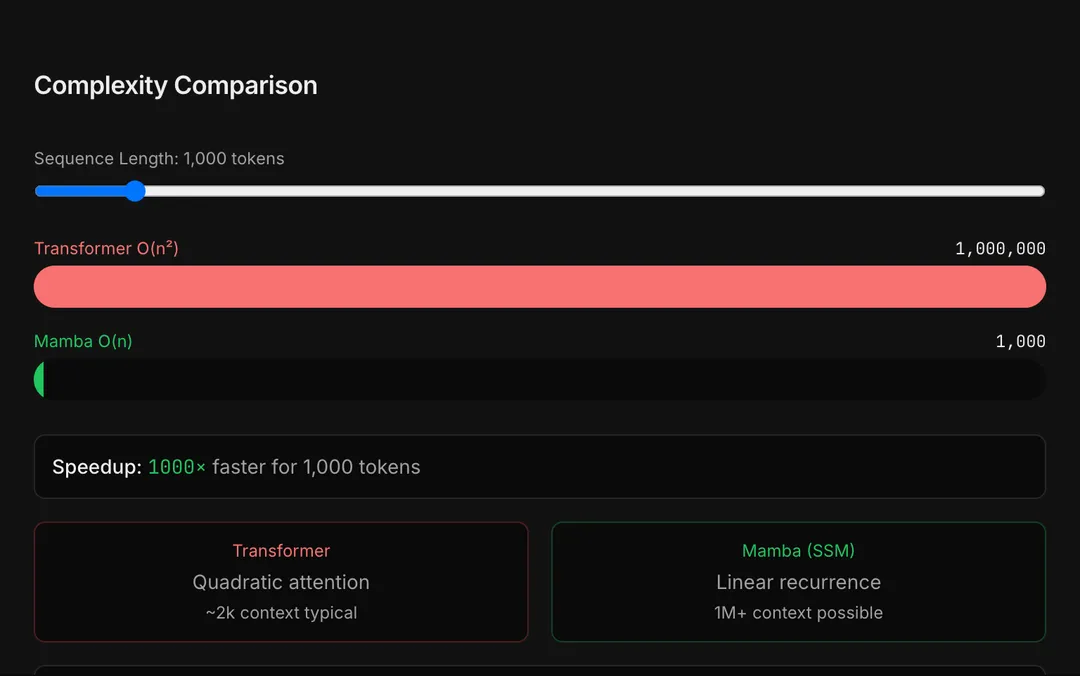
A sequence model that keeps a running state instead of attending to every token pair
Paper2018
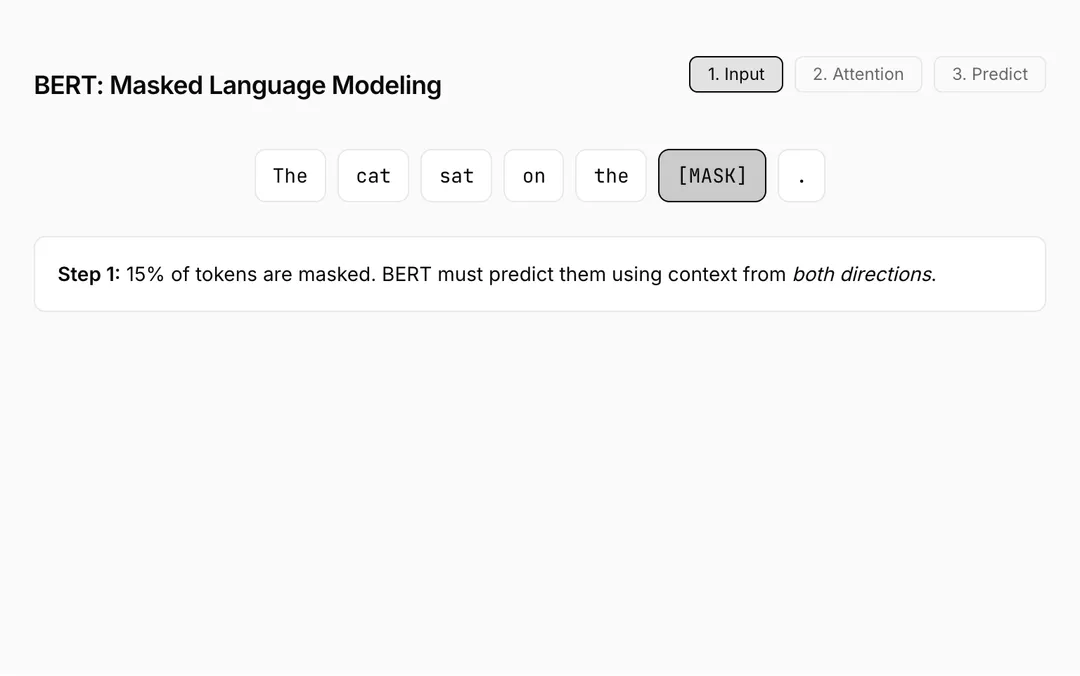
Devlin et al.
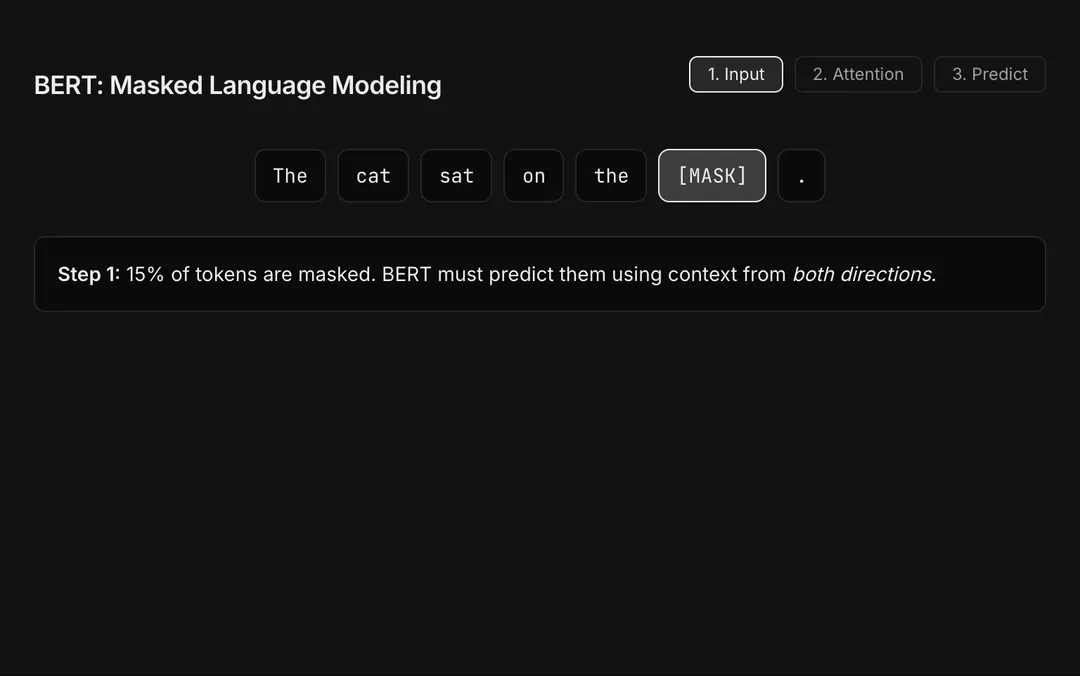
Pre-training deep bidirectional representations for NLP
Paper2018
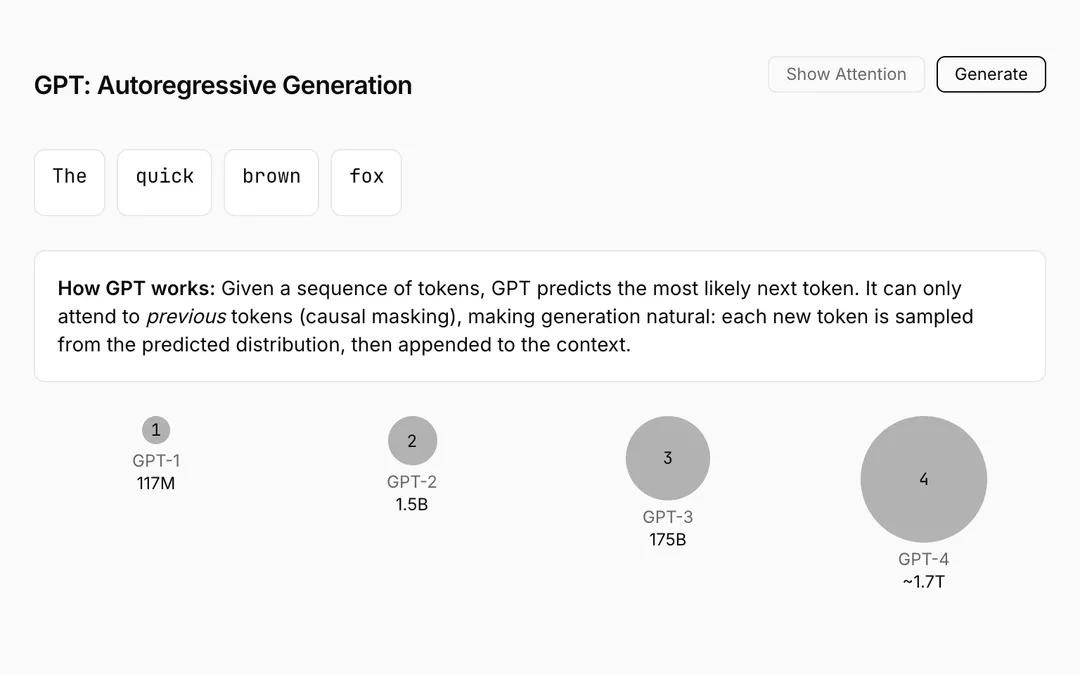
Radford et al.
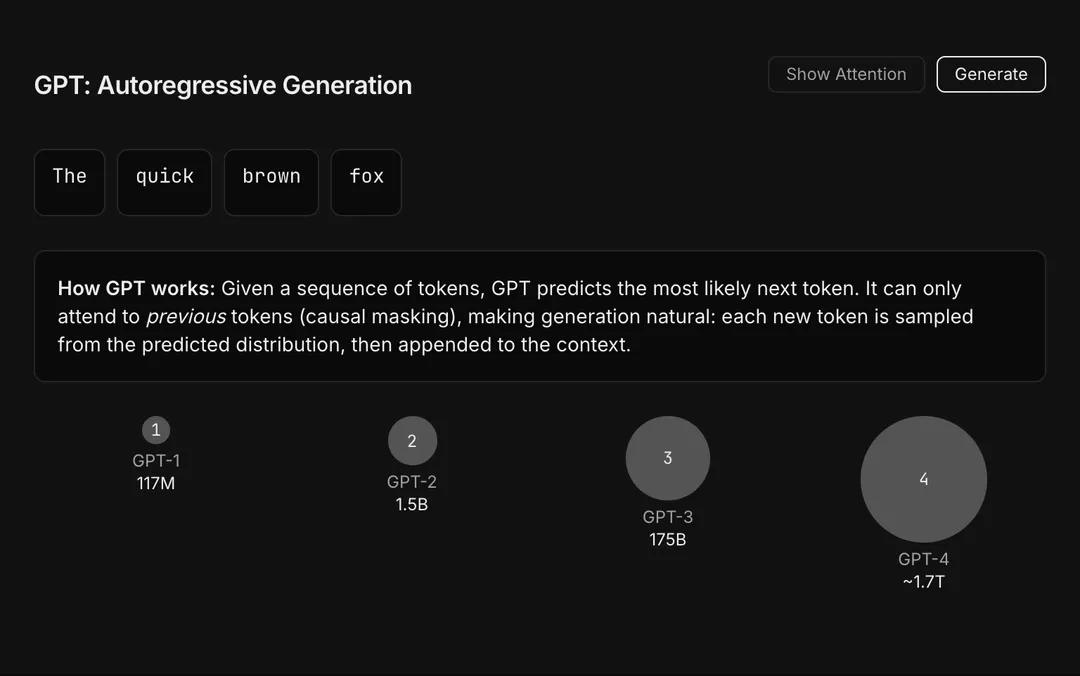
Autoregressive language models that learn to predict the next token
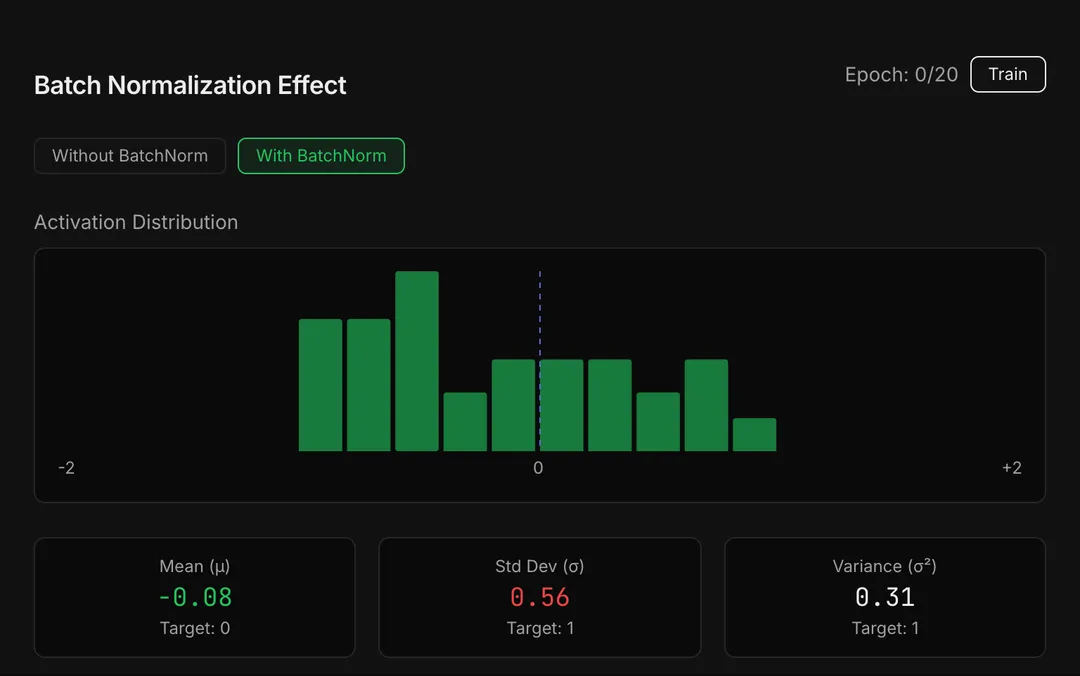
Concept2015
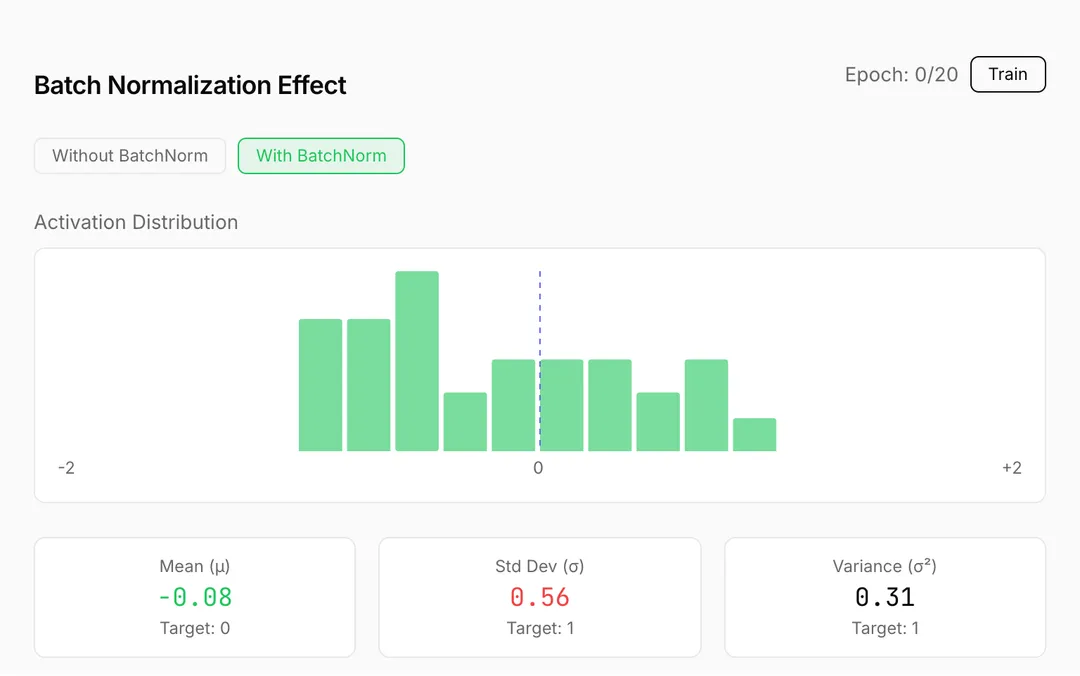
Ioffe & Szegedy
Normalizing layer inputs to accelerate deep network training
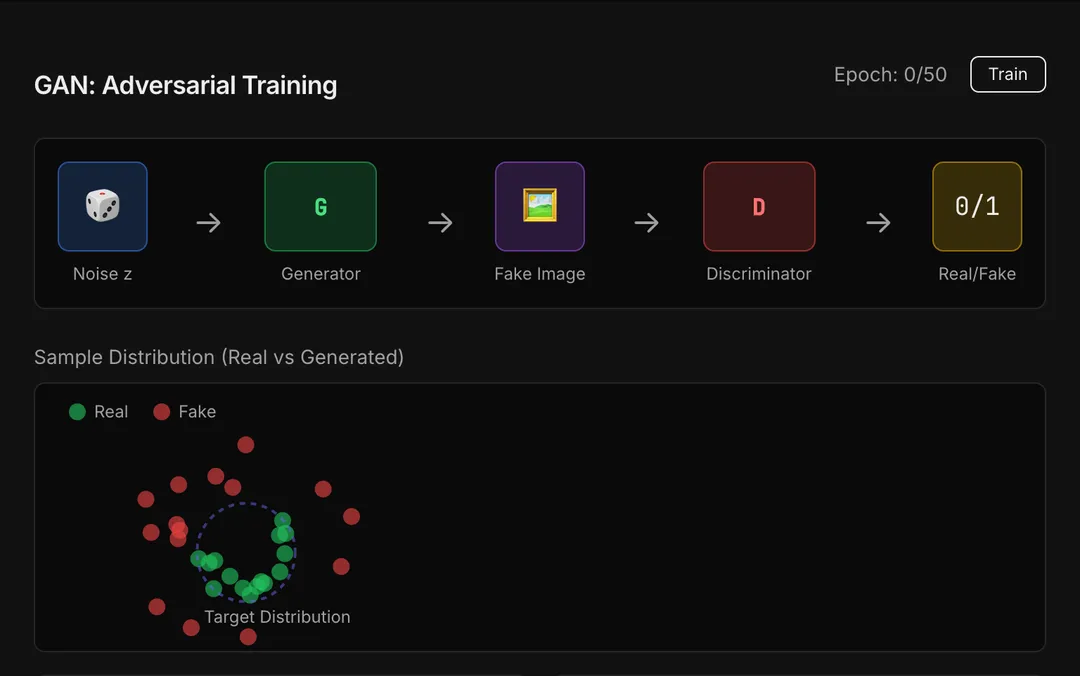
Concept2014
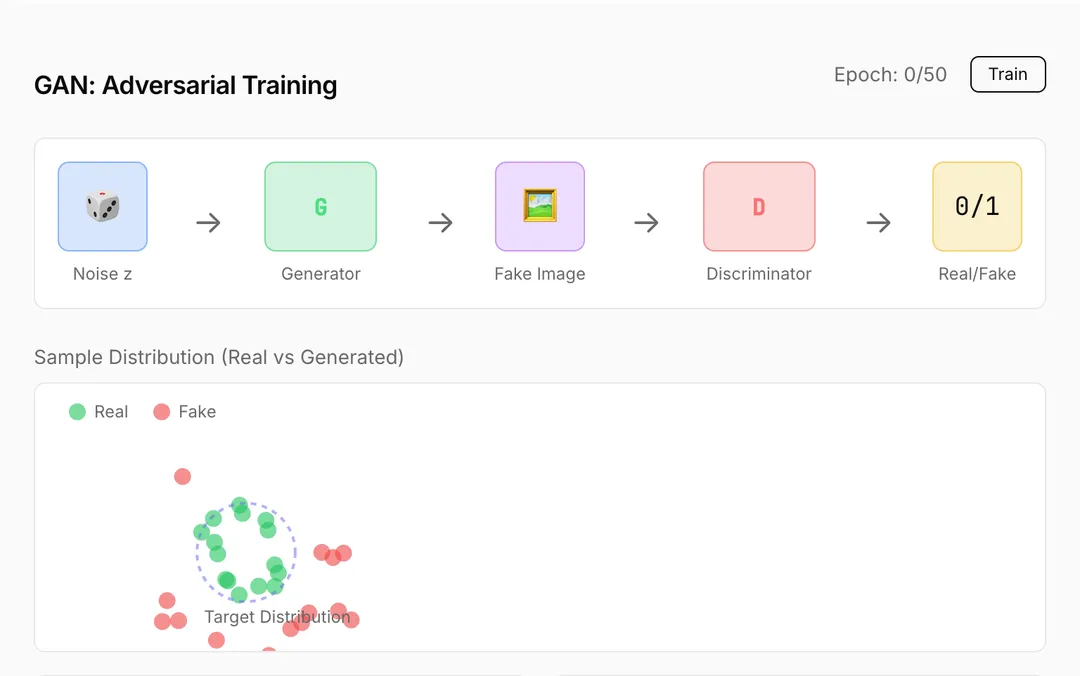
Goodfellow et al.
Two neural networks compete to generate realistic data
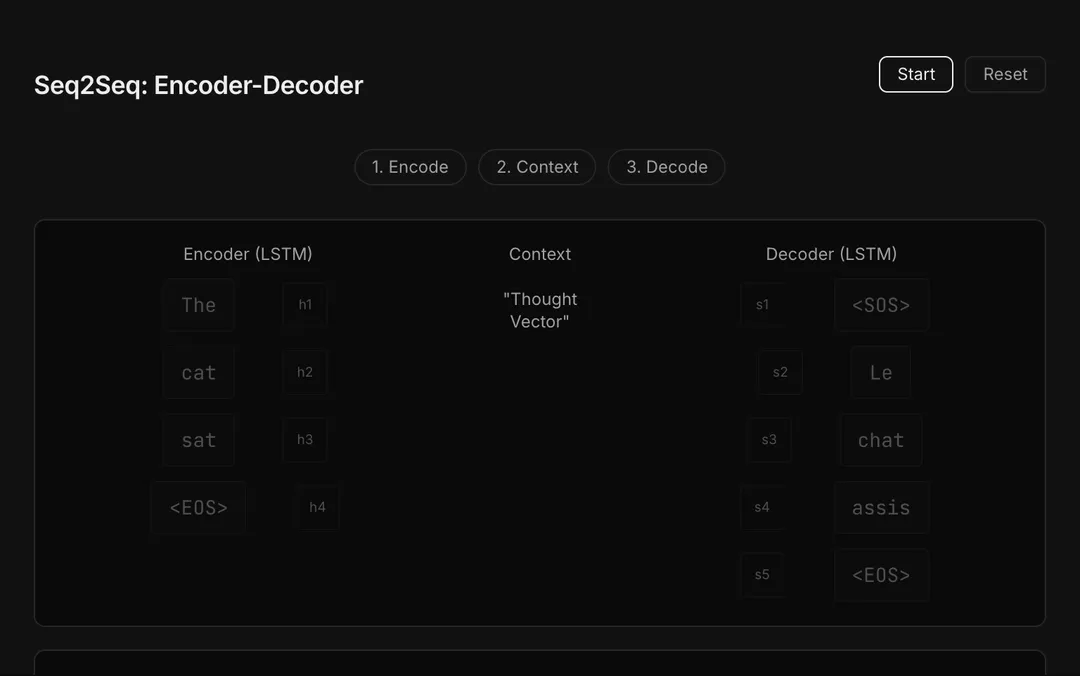
Paper2014
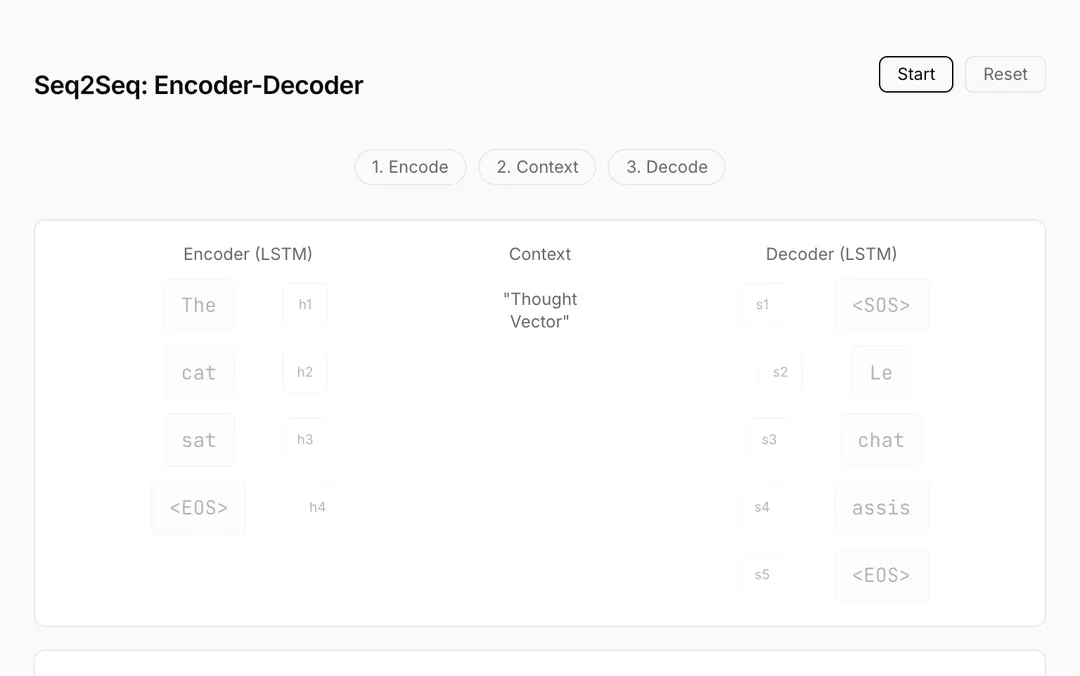
Sutskever, Vinyals & Le
Encoder-decoder architecture for mapping sequences to sequences