Paper2017
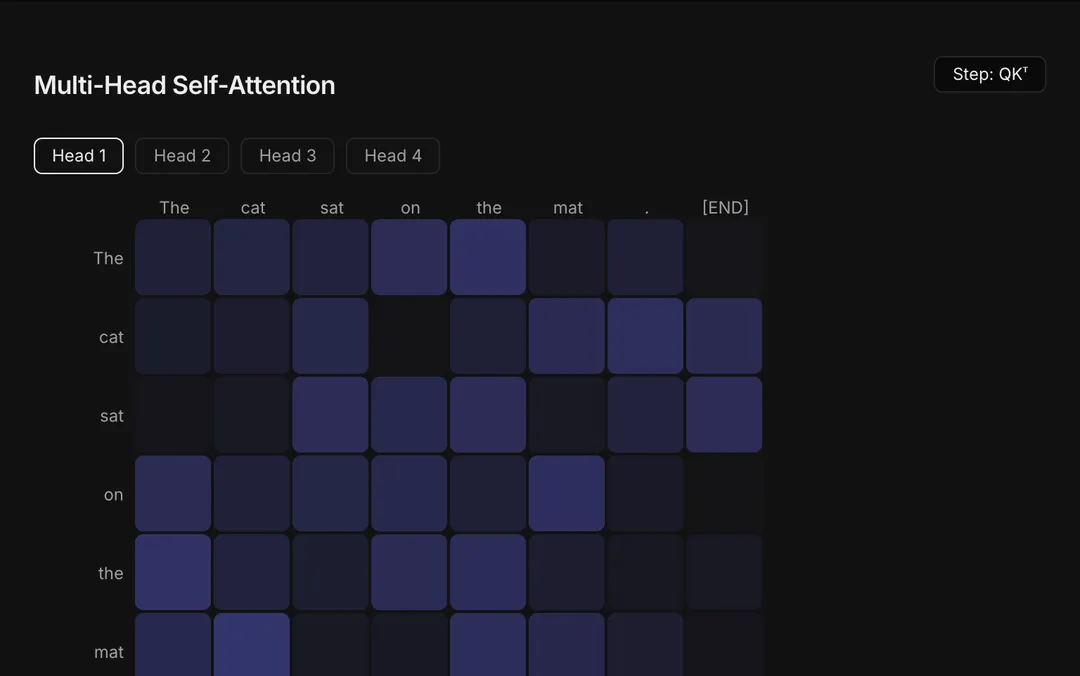
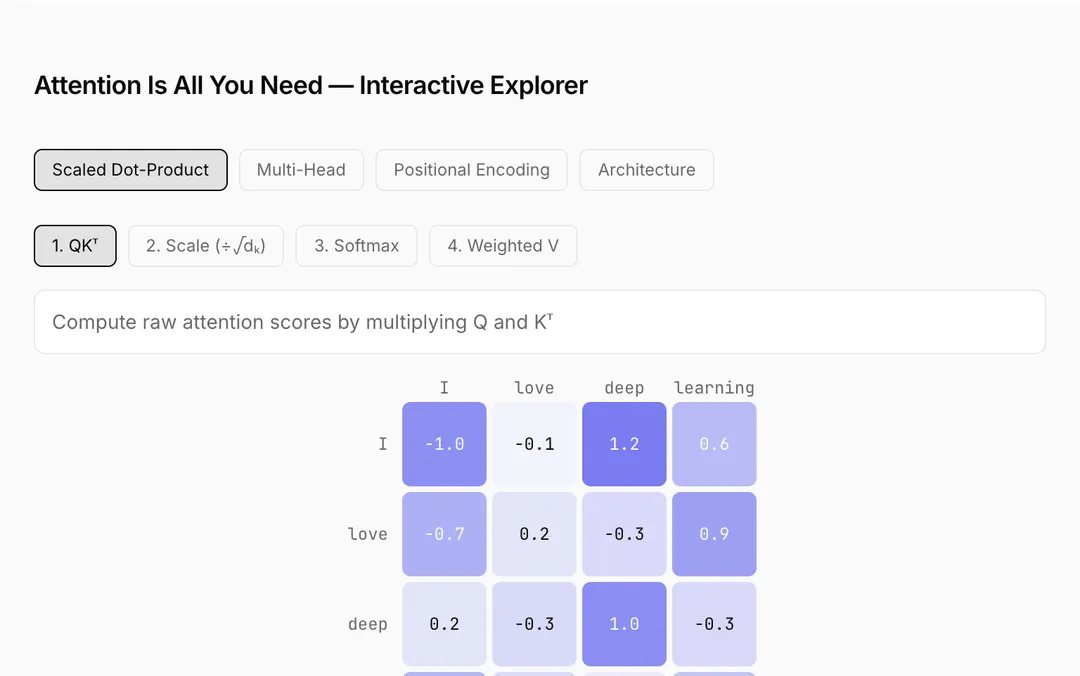
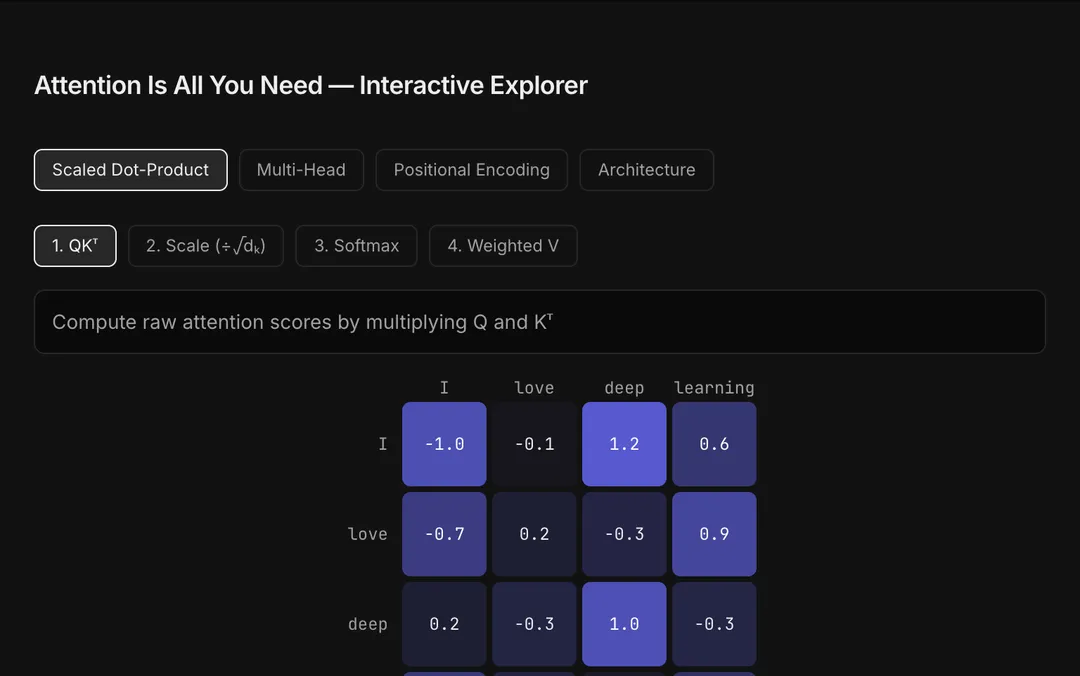
Attention Is All You Need
Vaswani et al.
The 2017 paper that introduced the Transformer architecture
15 entries / Filter in the index →
Paper2017
Vaswani et al.
The 2017 paper that introduced the Transformer architecture
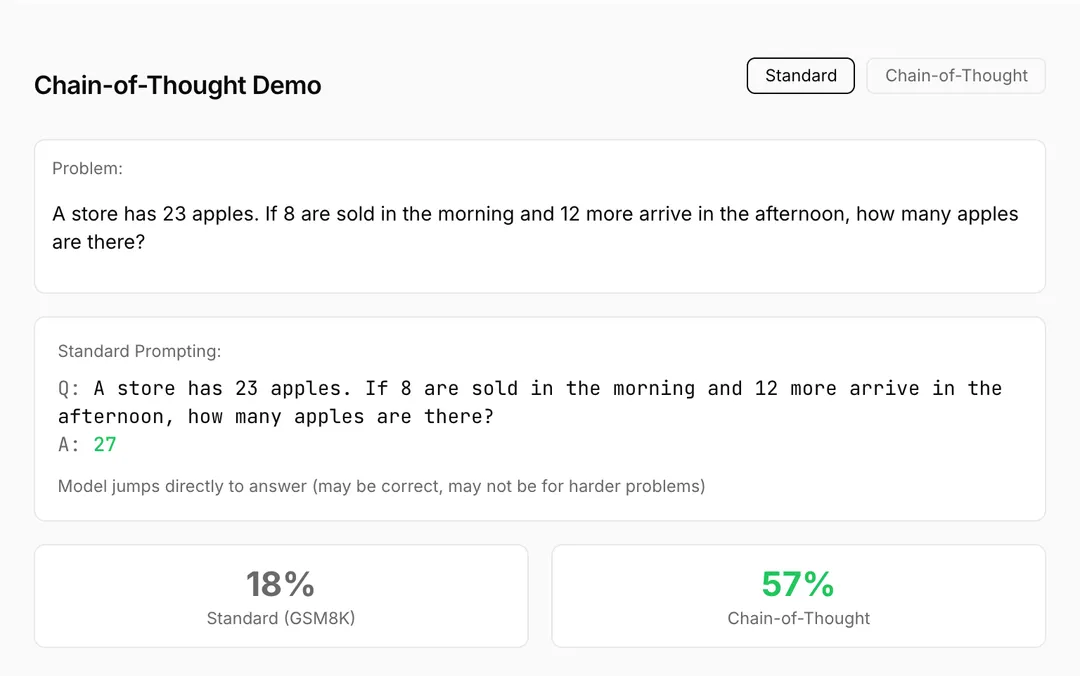
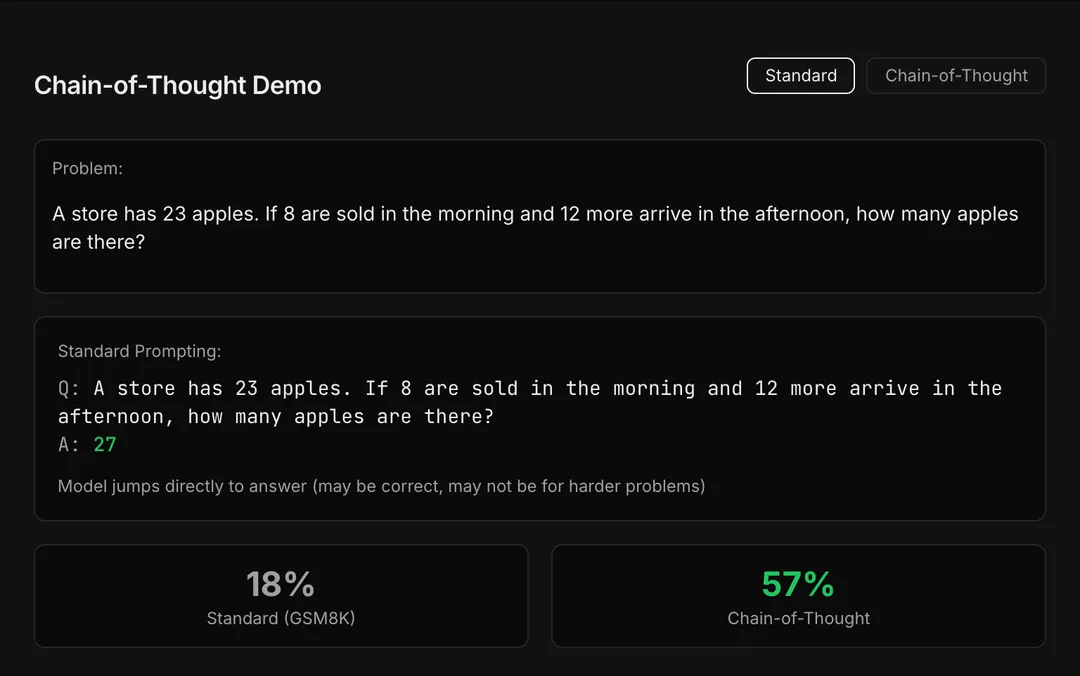
Concept2022
Wei et al.
Eliciting step-by-step reasoning in language models for complex problem solving
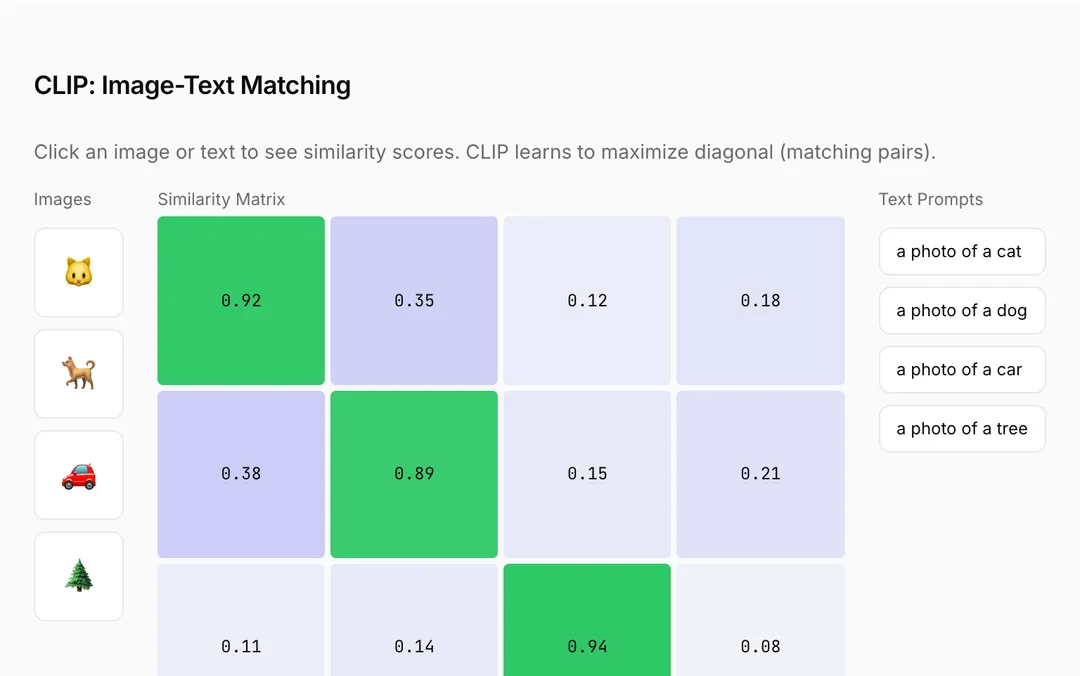
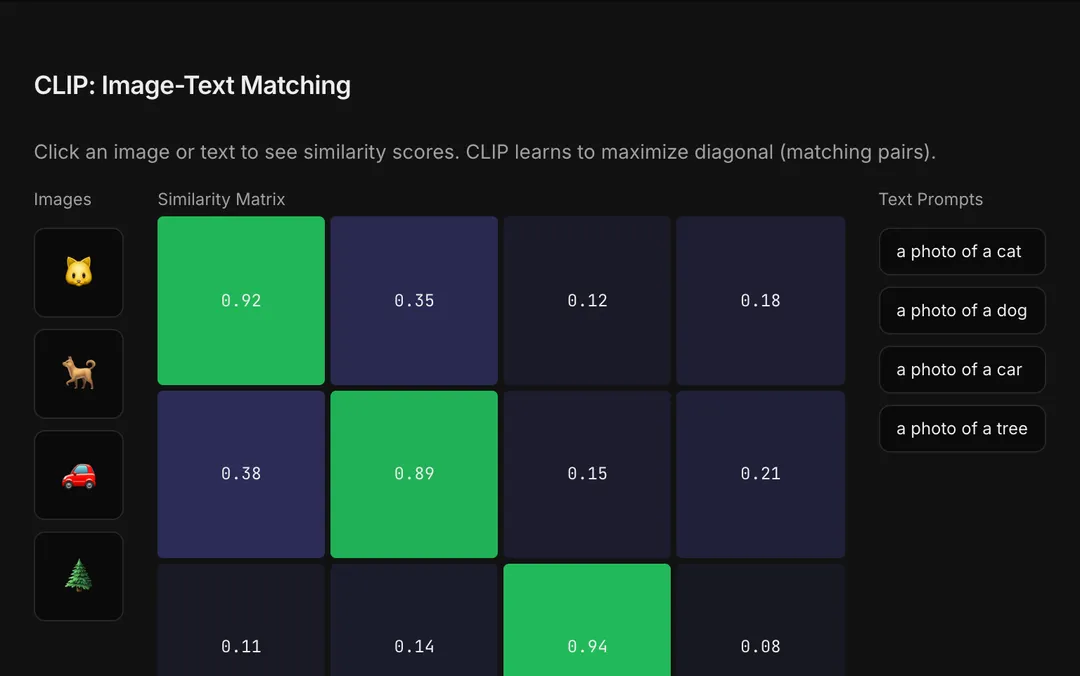
Paper2021
Radford et al.
Learning visual concepts from natural language supervision
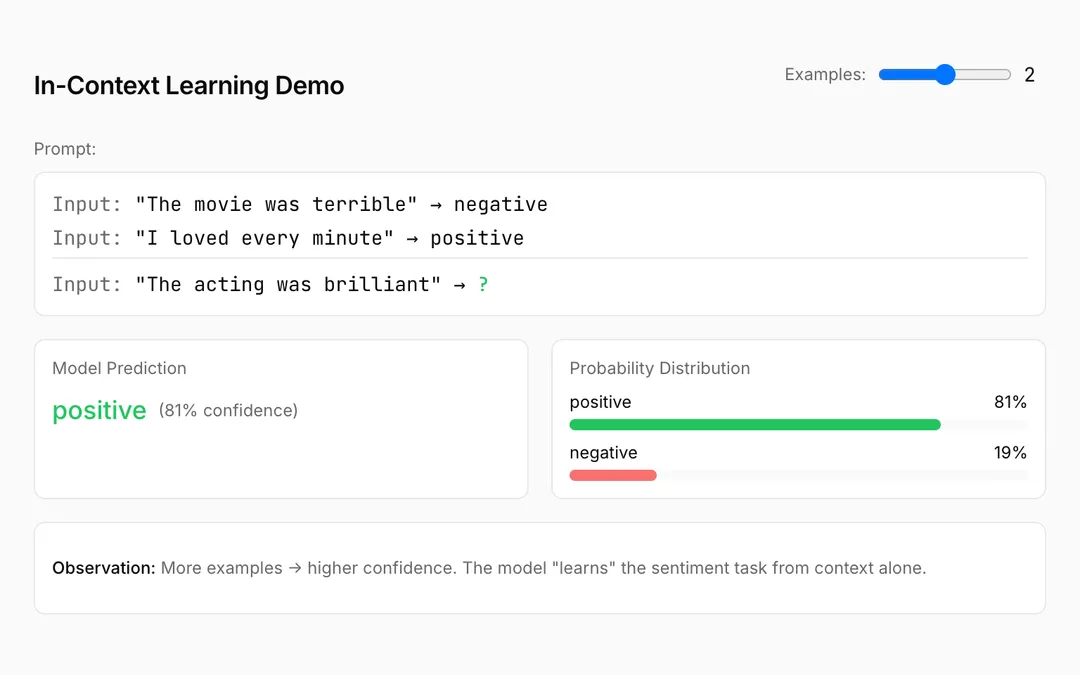
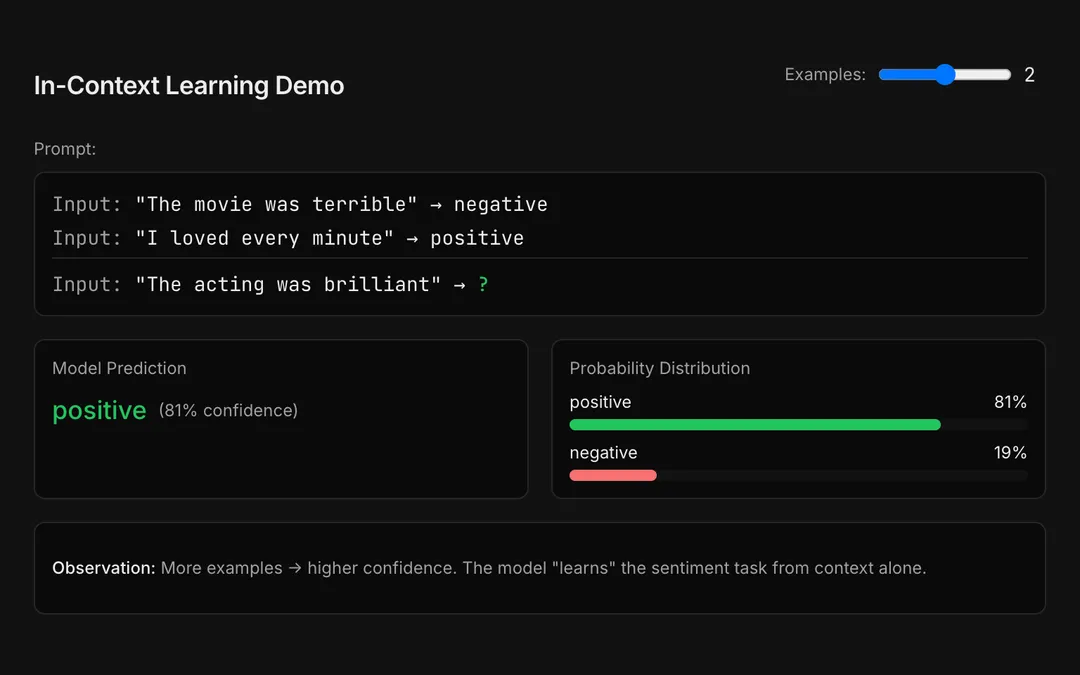
Concept2020
Brown et al.
How large language models learn from examples in the prompt without weight updates
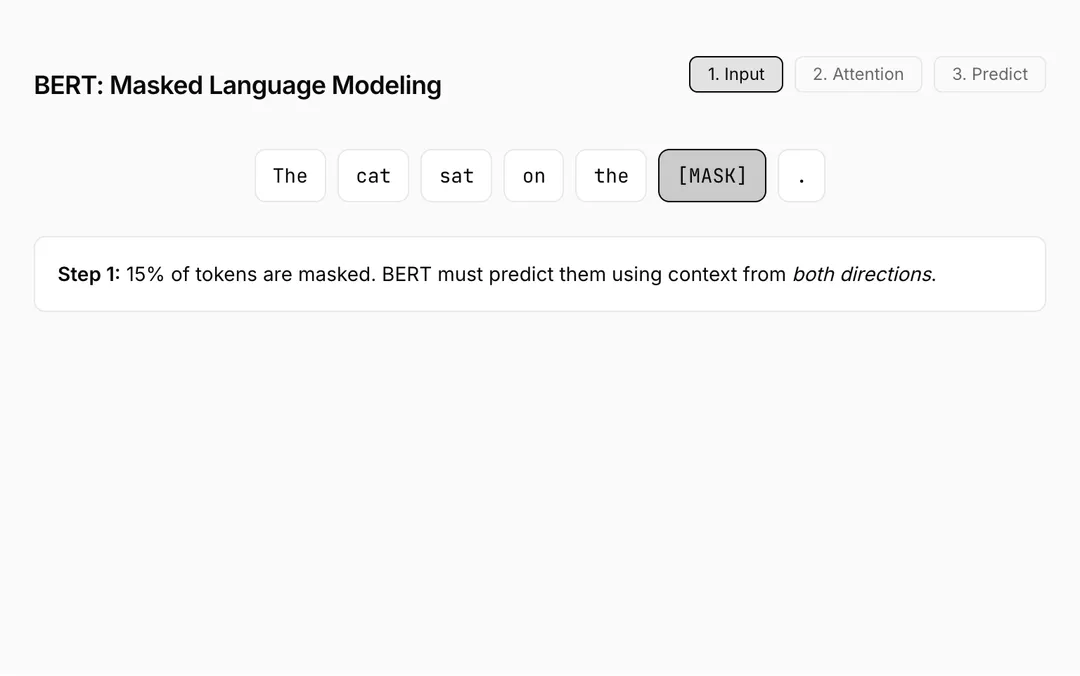
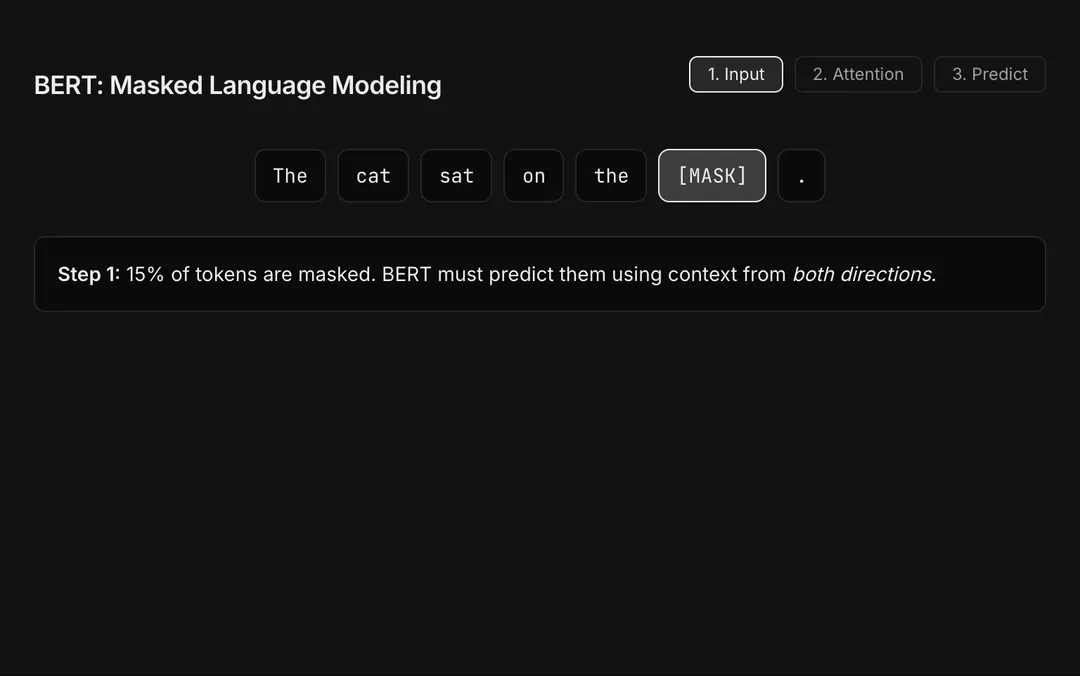
Paper2018
Devlin et al.
Pre-training deep bidirectional representations for NLP
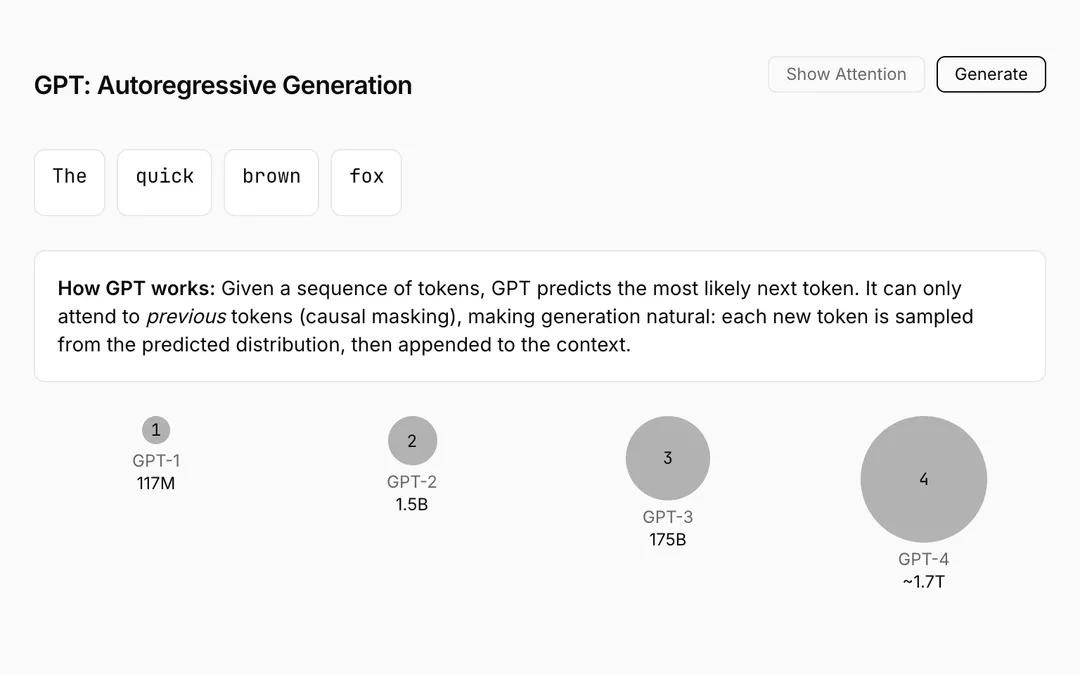
Paper2018
Radford et al.
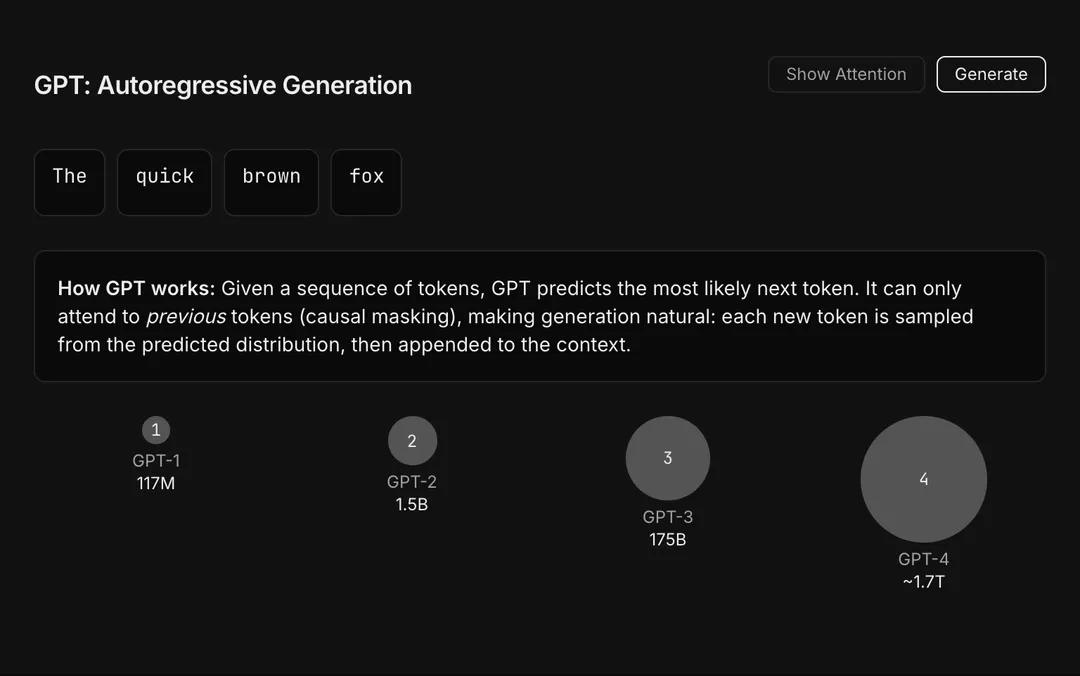
Autoregressive language models that learn to predict the next token
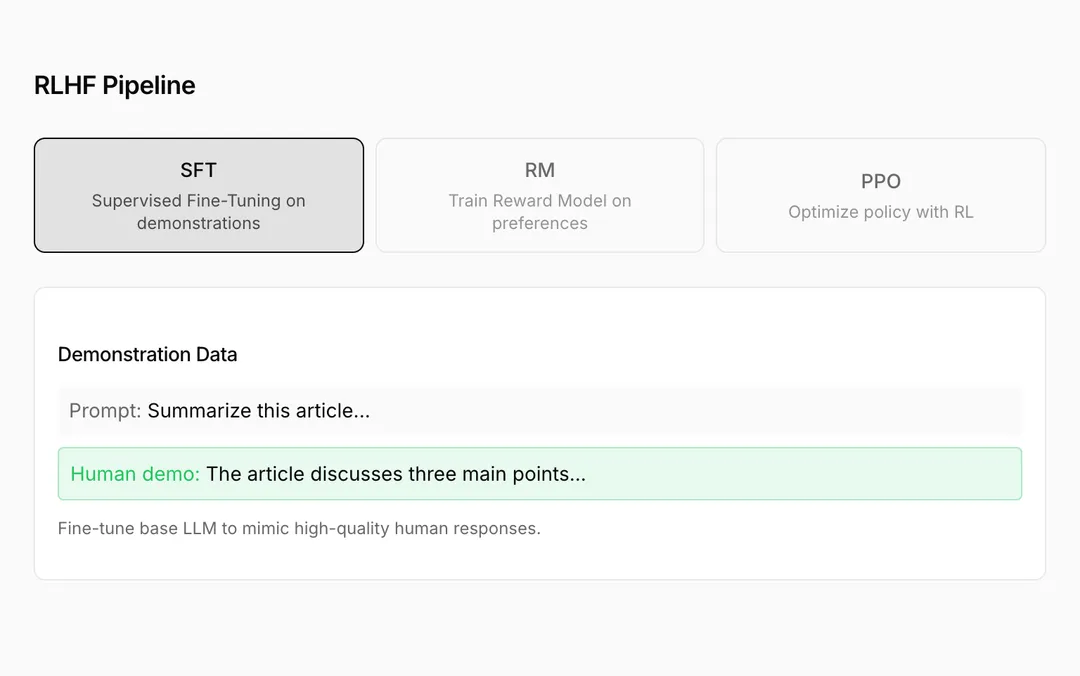
Concept2017
Christiano et al.
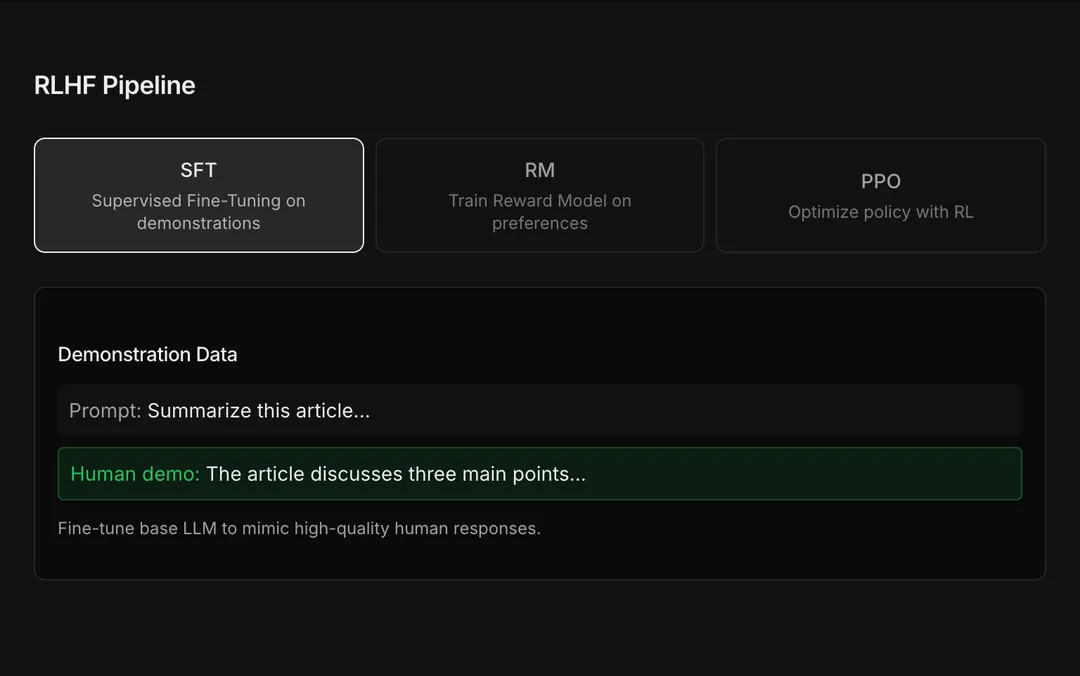
Teaching language models to prefer responses that people rank higher
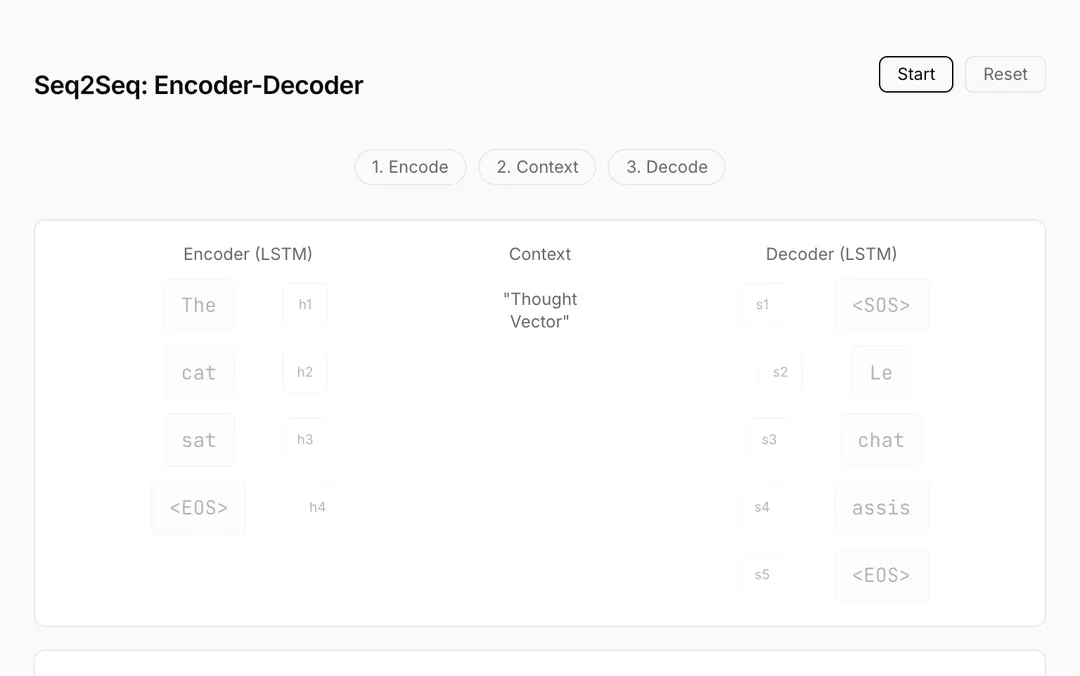
Paper2014
Sutskever, Vinyals & Le
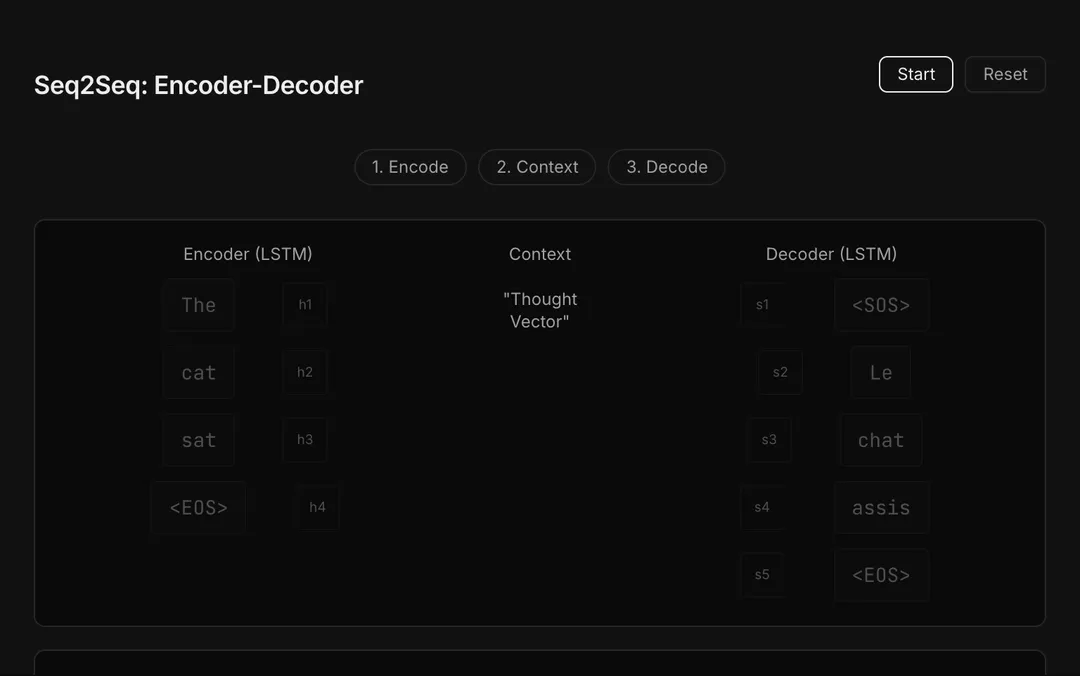
Encoder-decoder architecture for mapping sequences to sequences
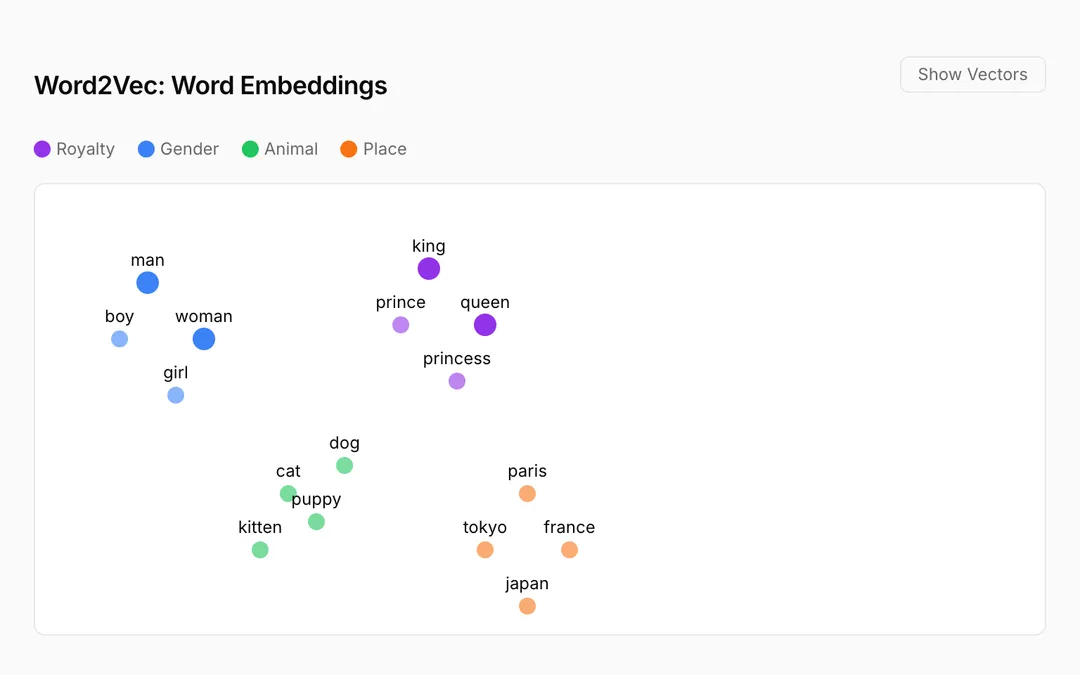
Concept2013
Mikolov et al.
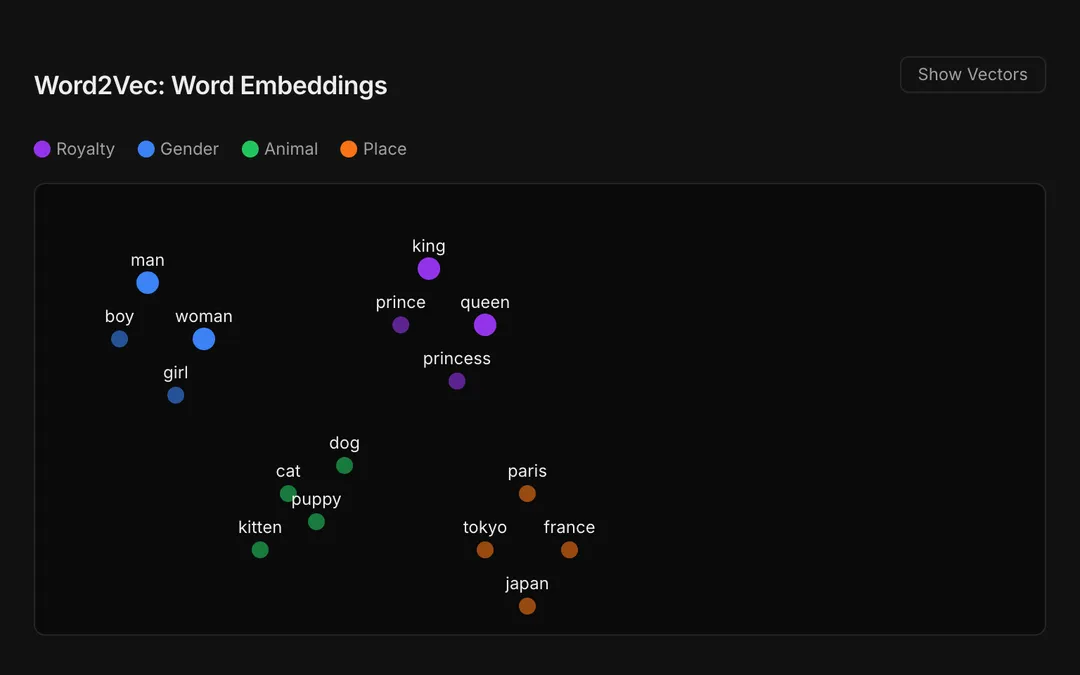
Learning dense vector representations of words from text
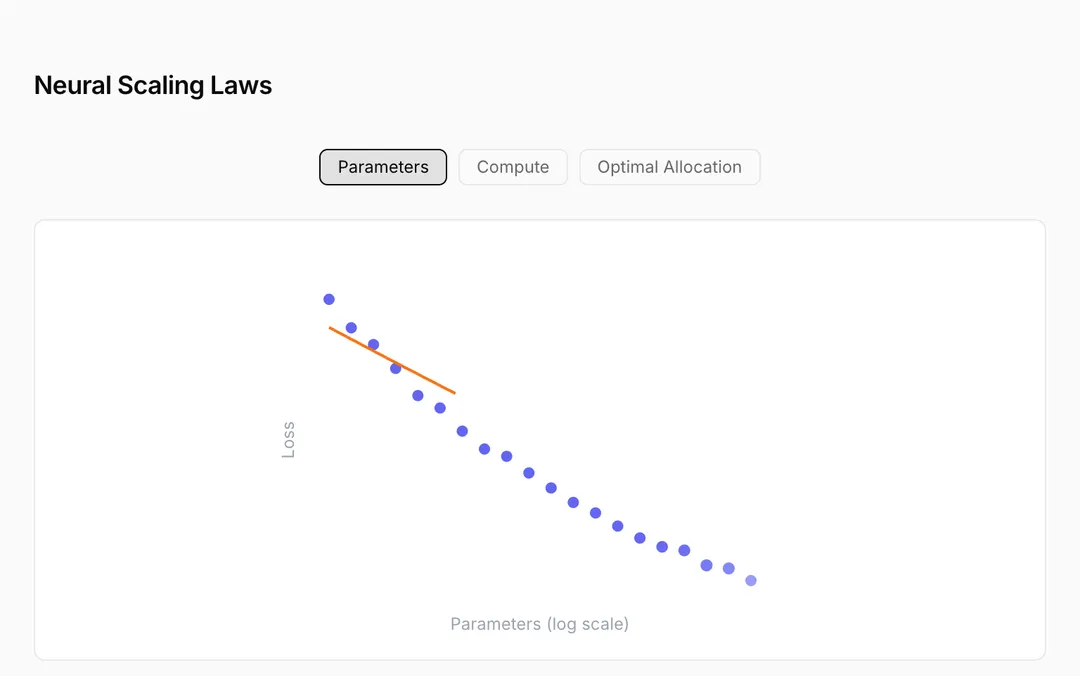
Paper2020
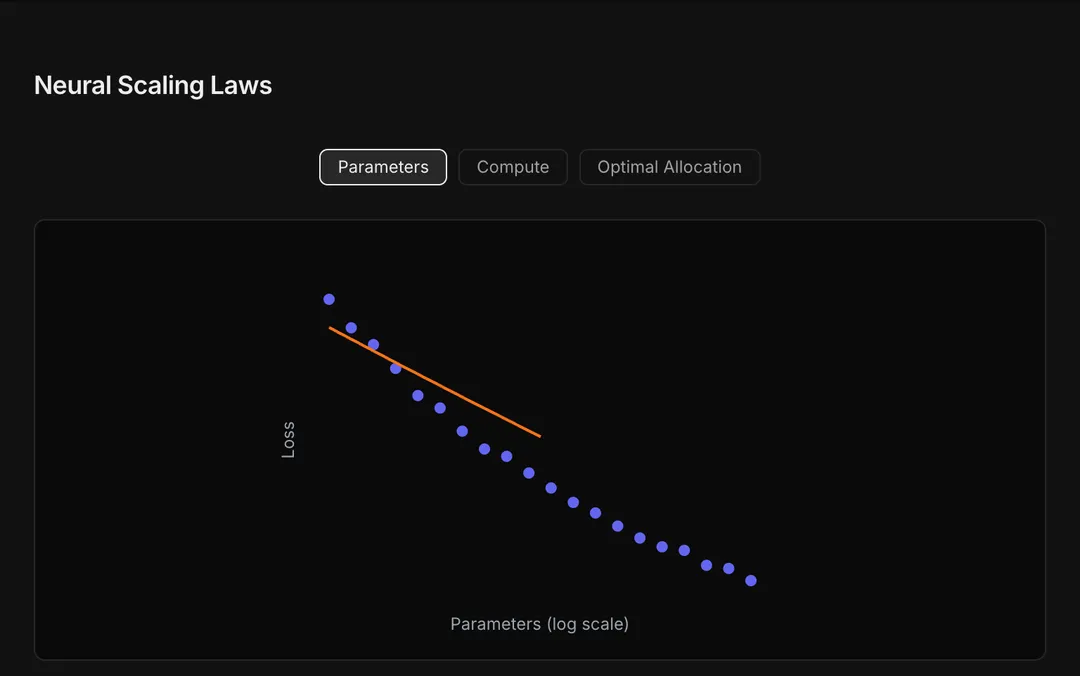
Kaplan et al.
Why bigger models, more data, and more compute lead to predictable gains
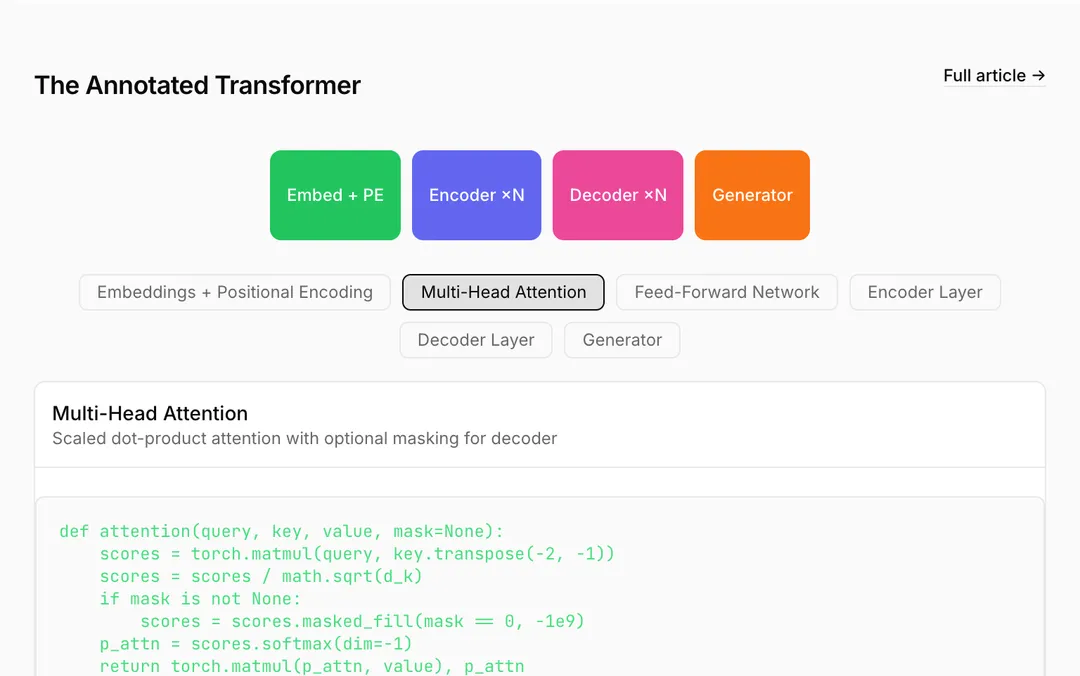
Blog2018
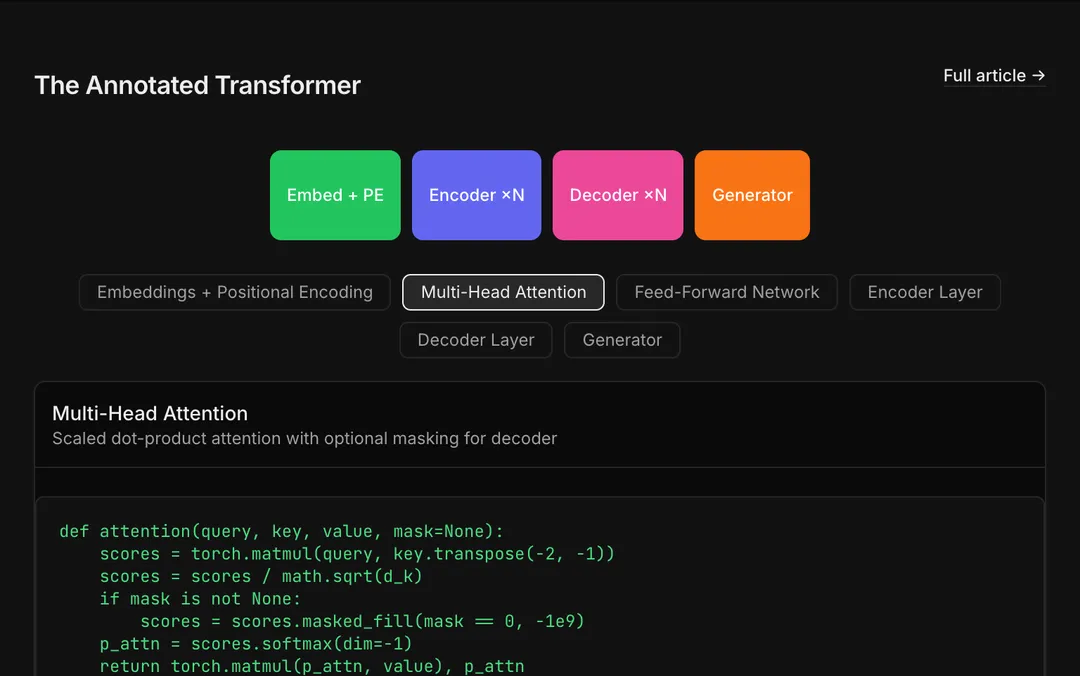
Sasha Rush
Line-by-line PyTorch implementation of the Transformer architecture
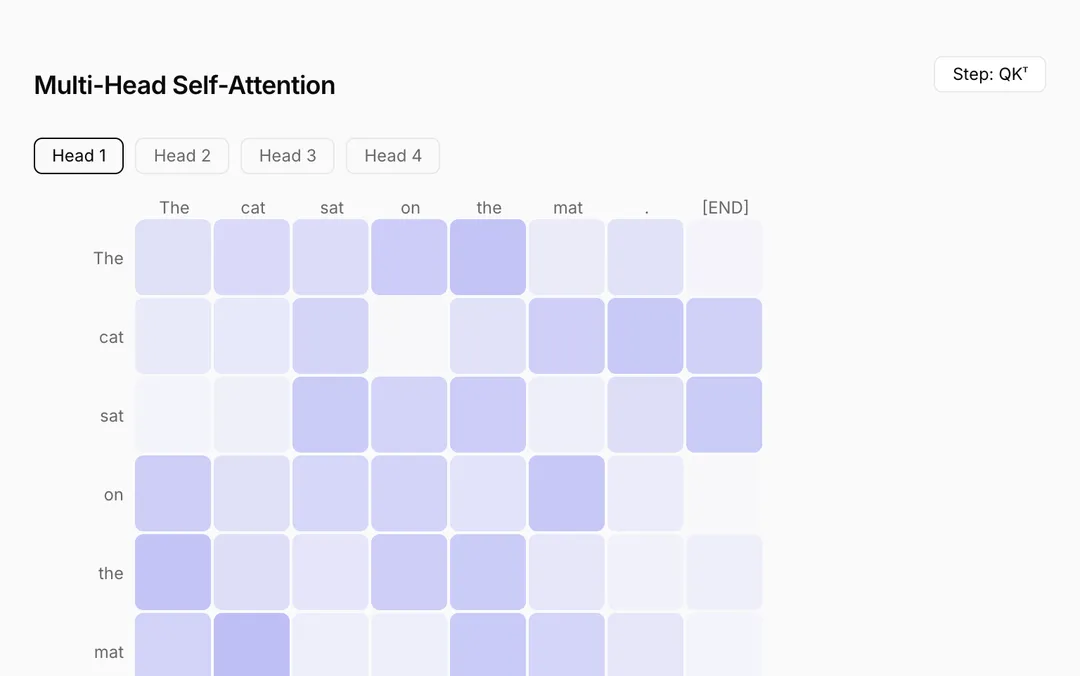
Blog2015
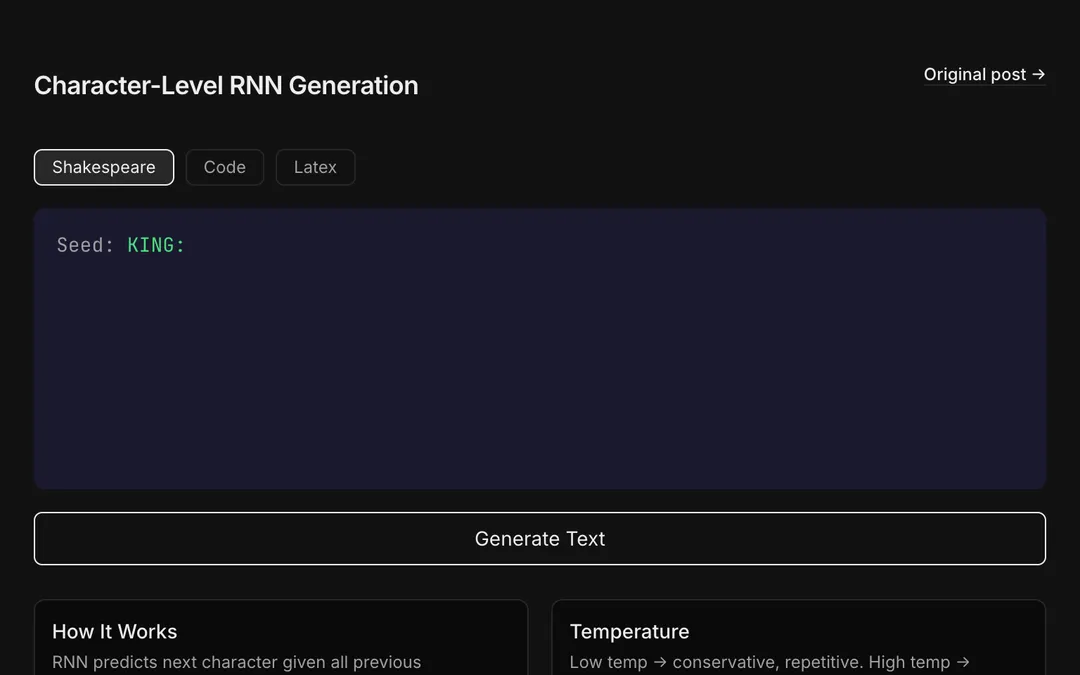
Andrej Karpathy
Andrej Karpathy's influential blog post demonstrating RNN capabilities through character-level generation
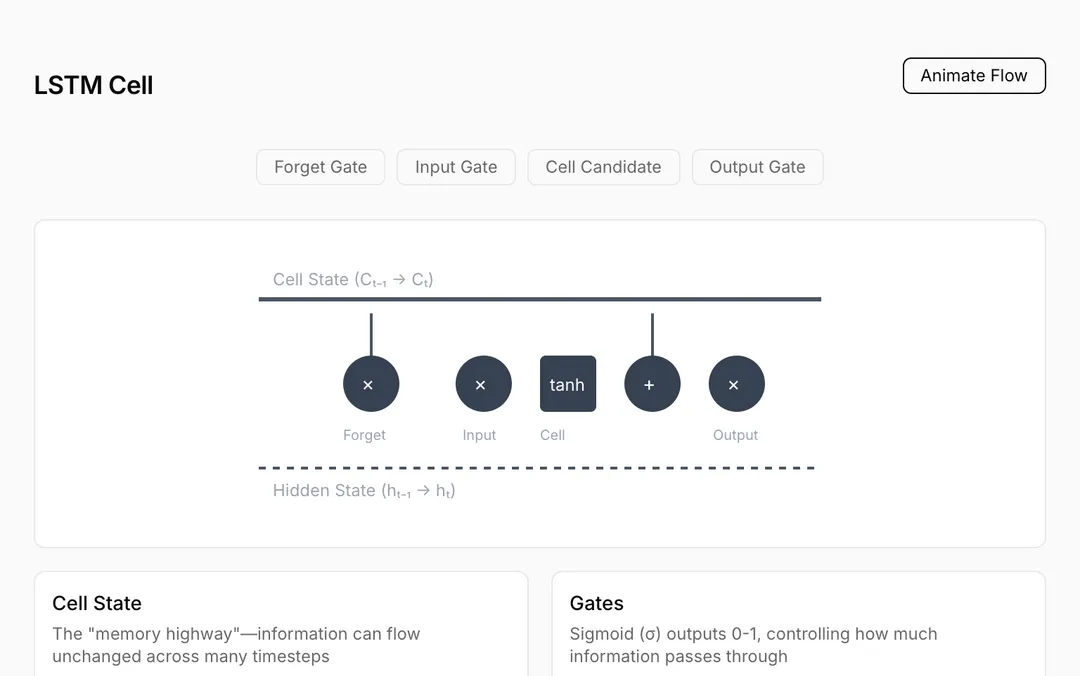
Blog2015
Chris Olah
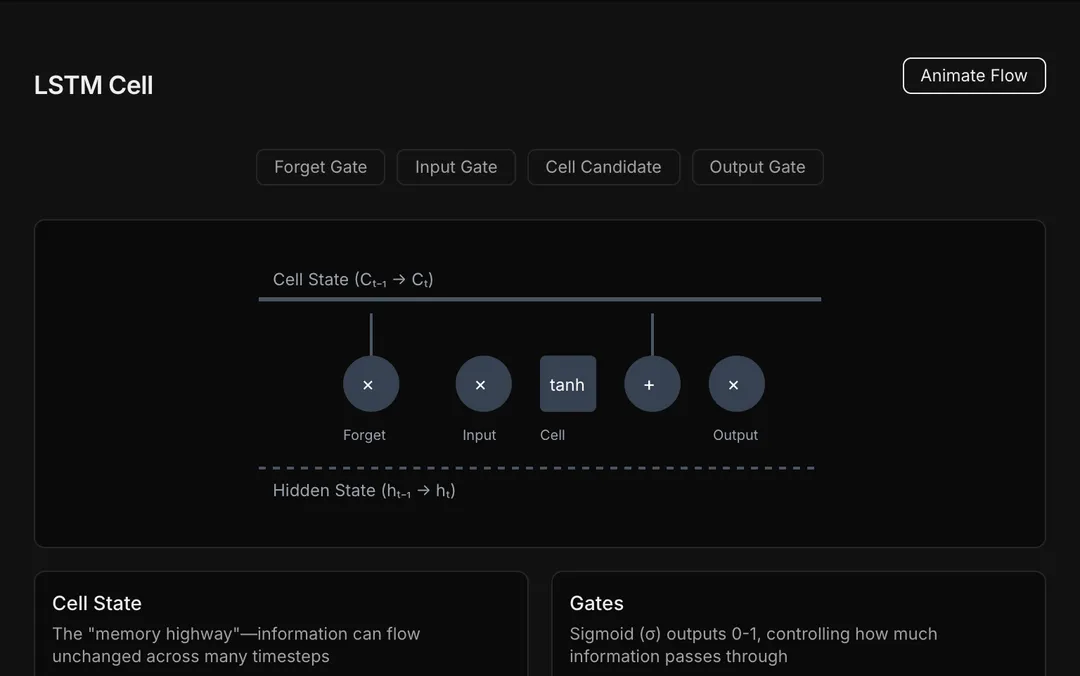
Christopher Olah's visual guide to Long Short-Term Memory networks
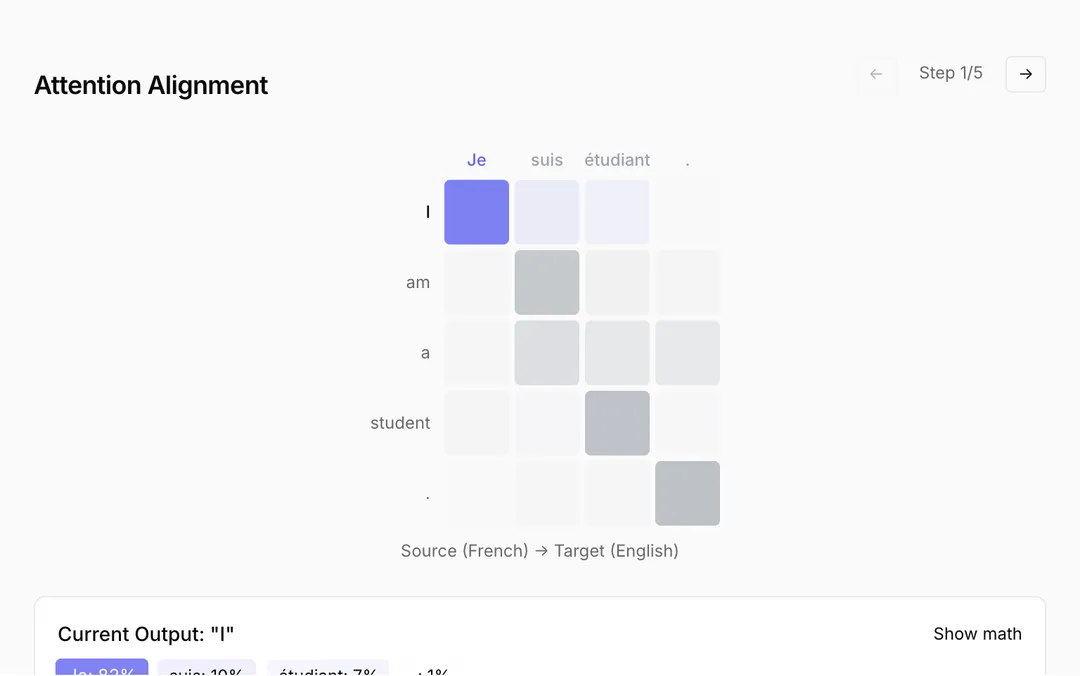
Paper2014
Bahdanau, Cho & Bengio
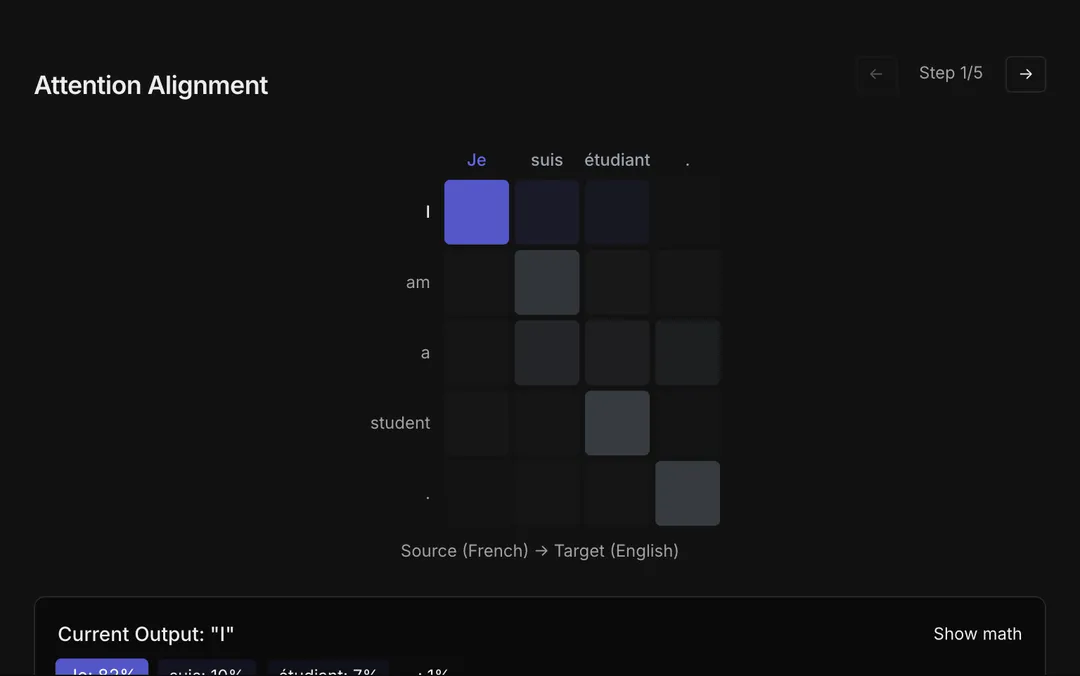
The paper that introduced the attention mechanism for sequence-to-sequence models