Paper2026
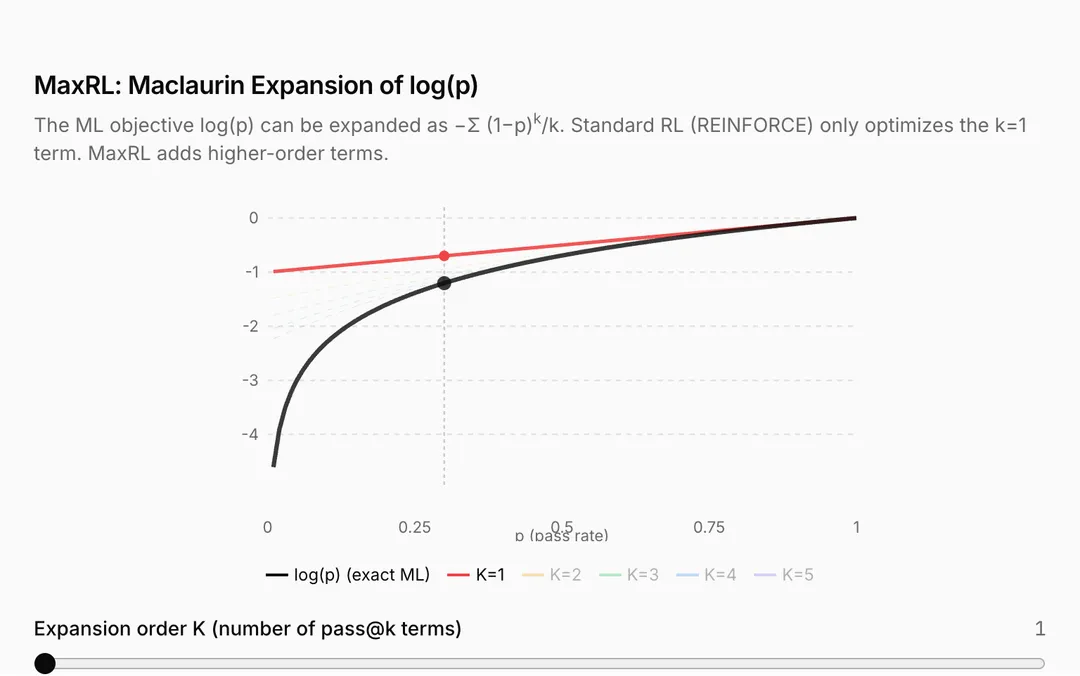
Maximum Likelihood Reinforcement Learning (MaxRL)
Tajwar et al.
A recent idea for training models on pass-fail tasks when sampling matters
7 entries / Filter in the index →
Paper2026
Tajwar et al.
A recent idea for training models on pass-fail tasks when sampling matters
Concept2017
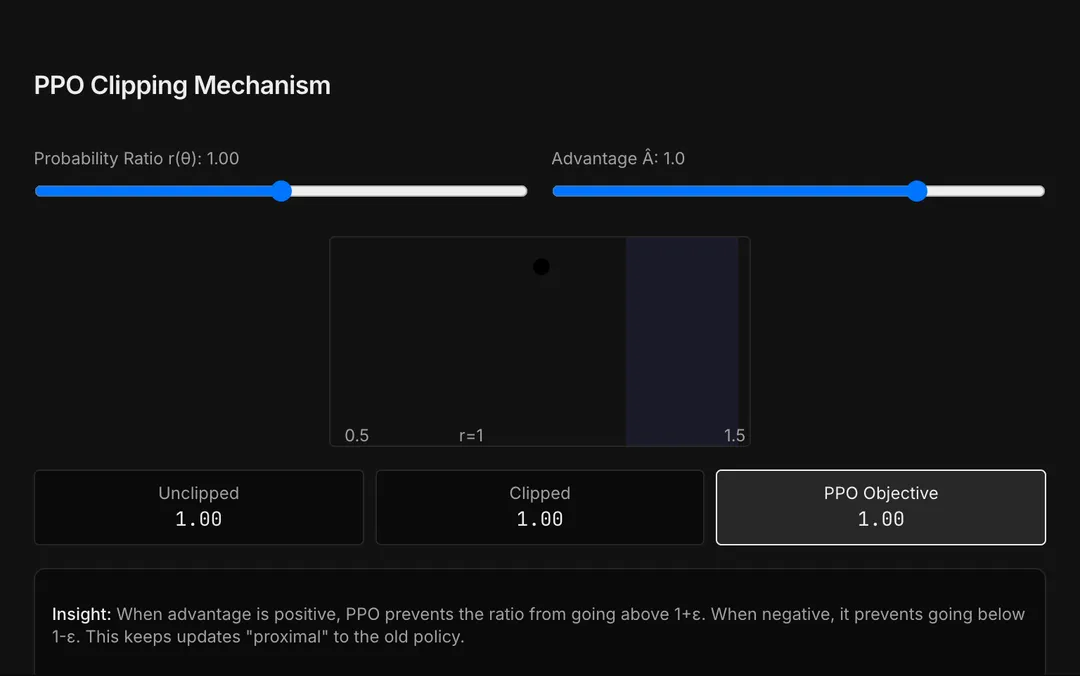
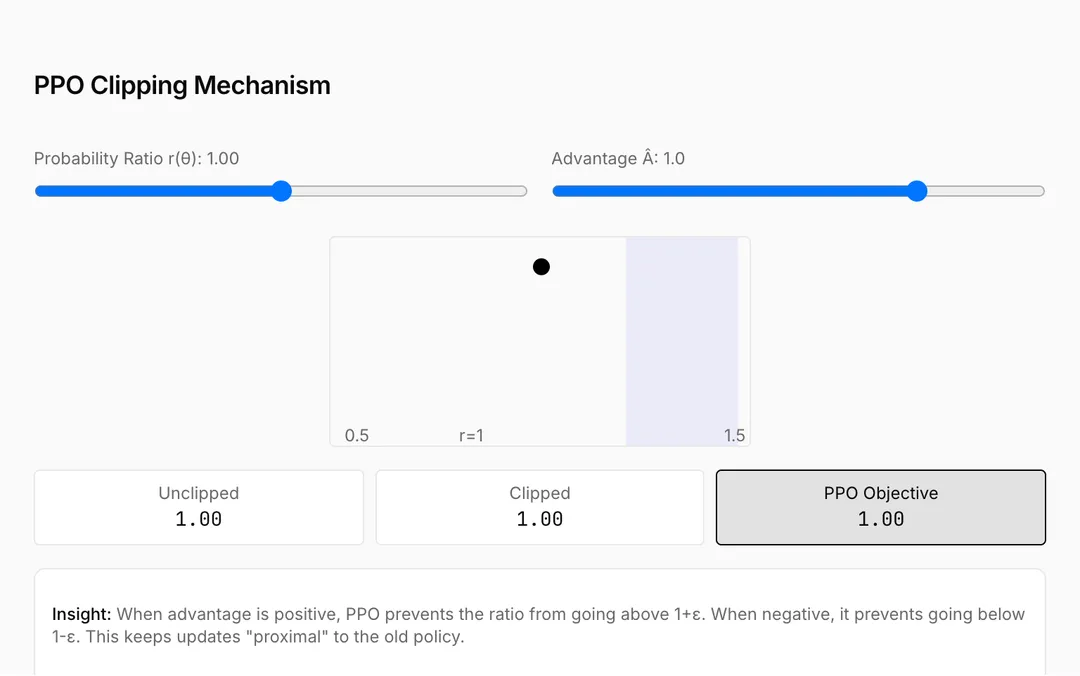
Schulman et al.
A stable, sample-efficient policy gradient algorithm for reinforcement learning
Concept2017
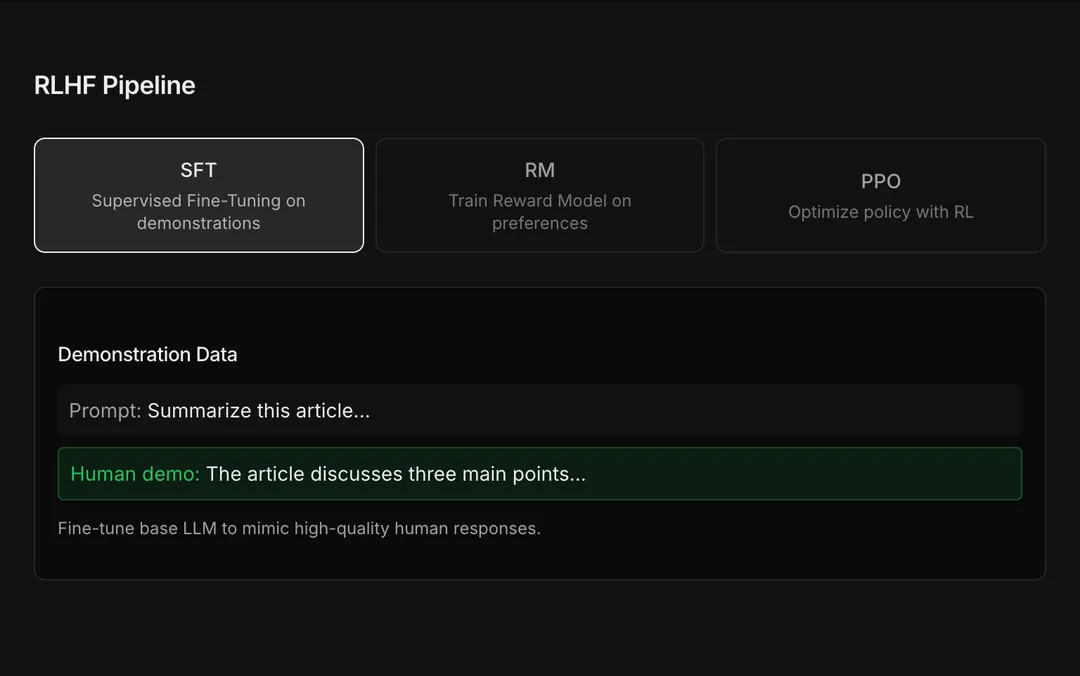
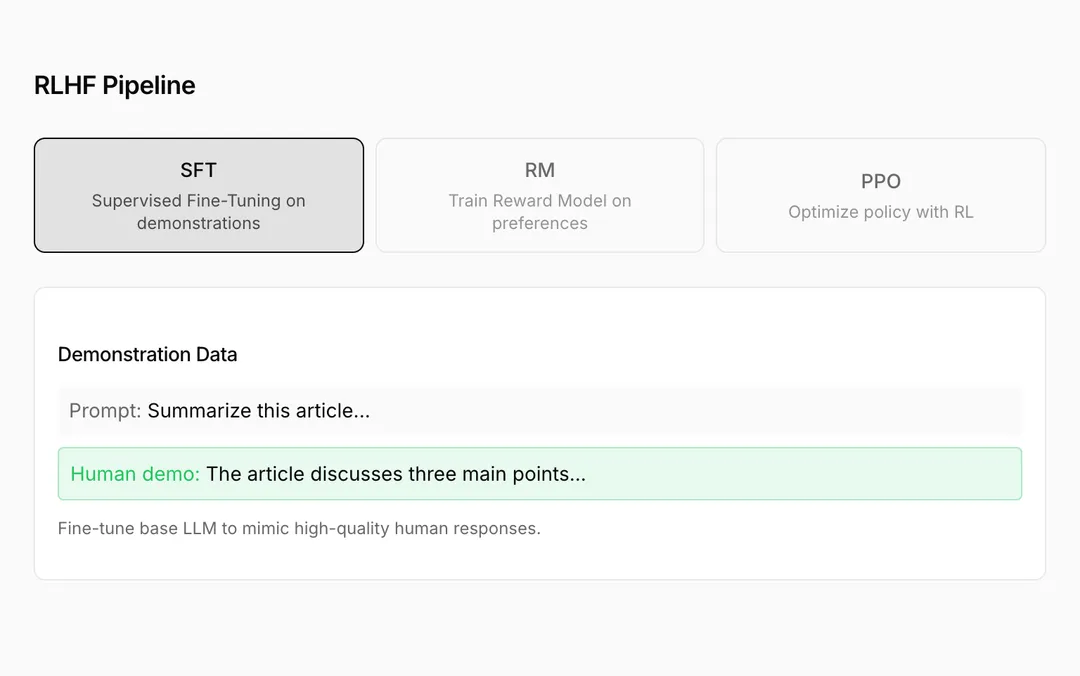
Christiano et al.
Teaching language models to prefer responses that people rank higher
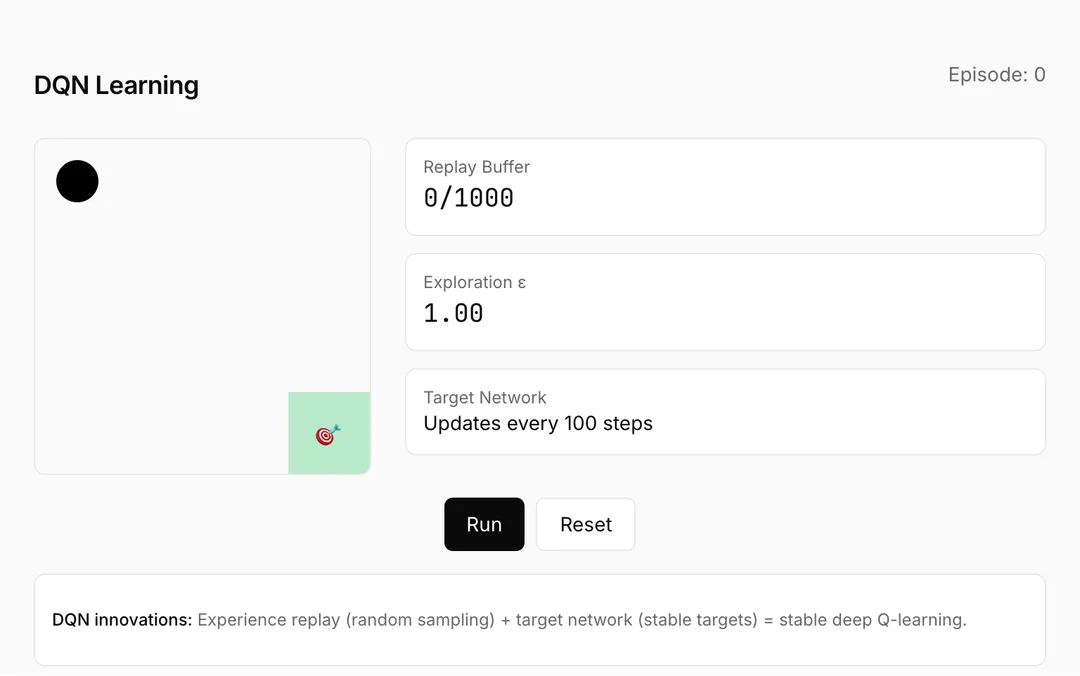
Paper2013
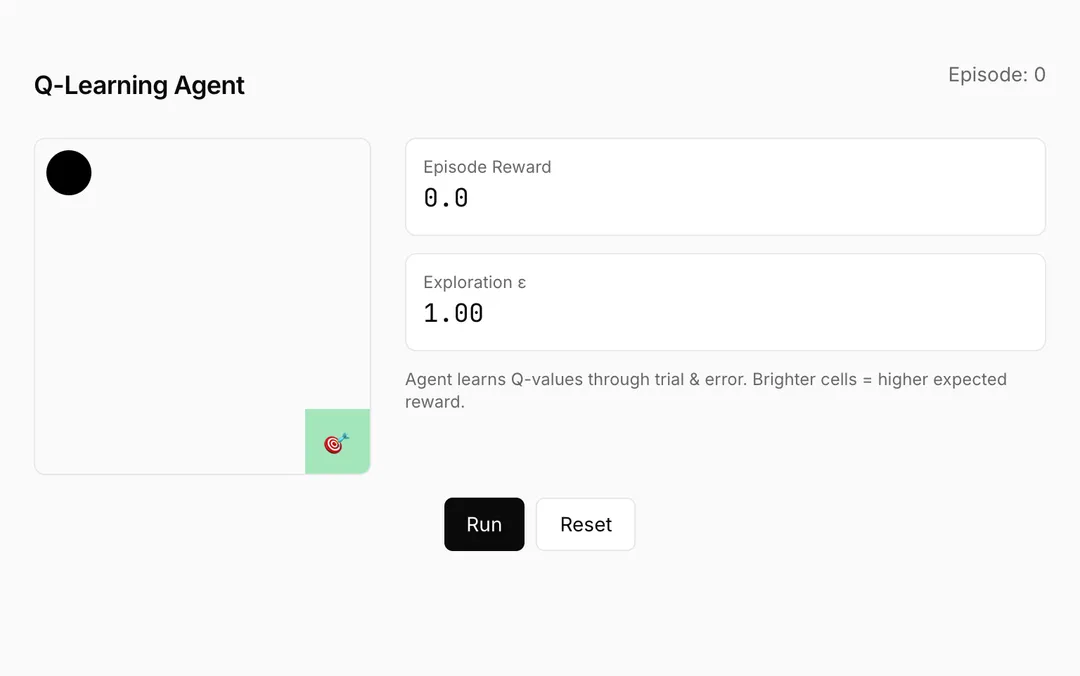
Mnih et al.
Combining Q-learning with deep neural networks for Atari-level game playing
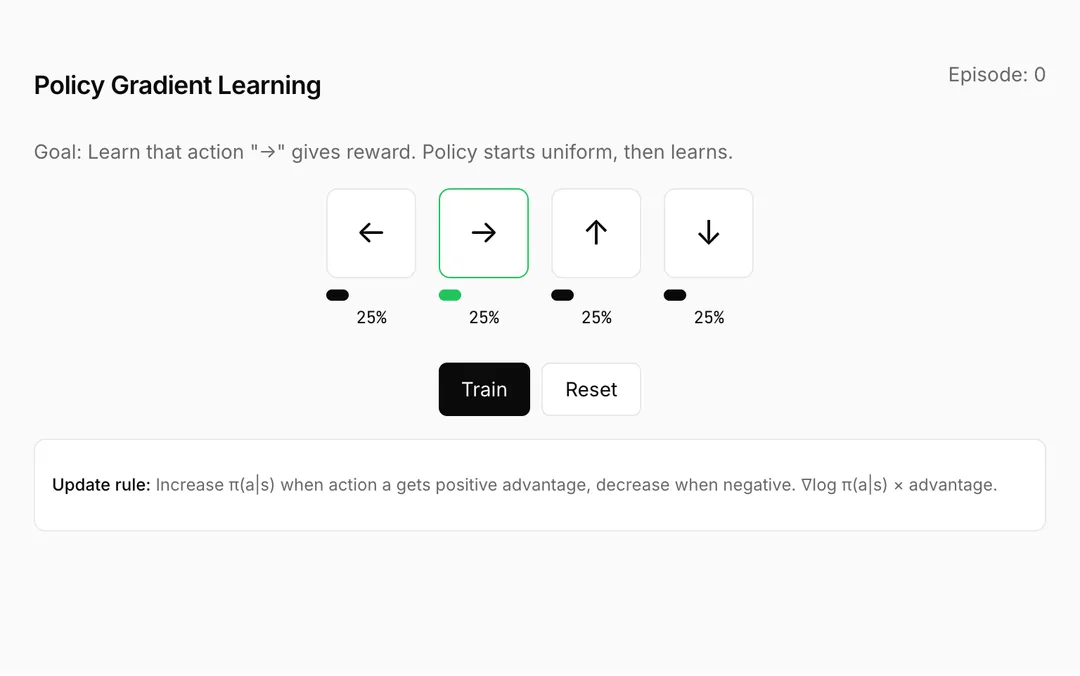
Concept1992
Williams
Directly optimizing policies through gradient ascent on expected returns